
SGLang6 min read
Accelerating vision-language models with LFM2.5-VL-DSpark
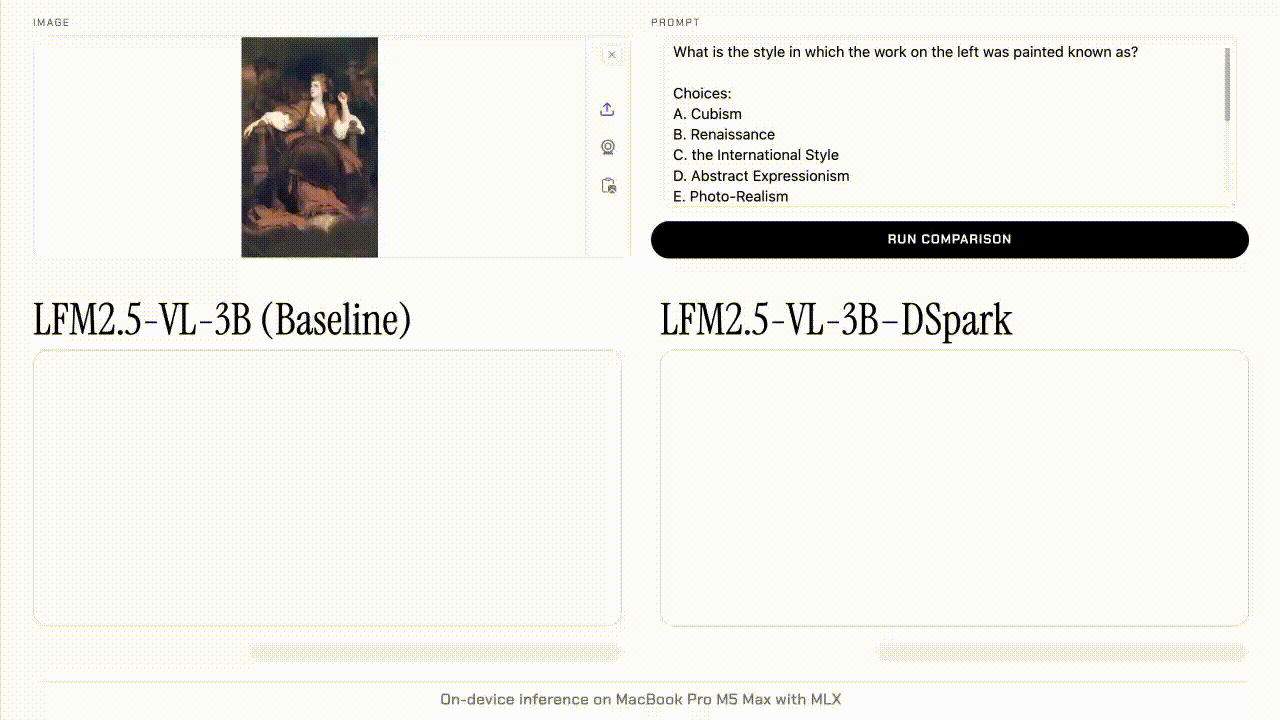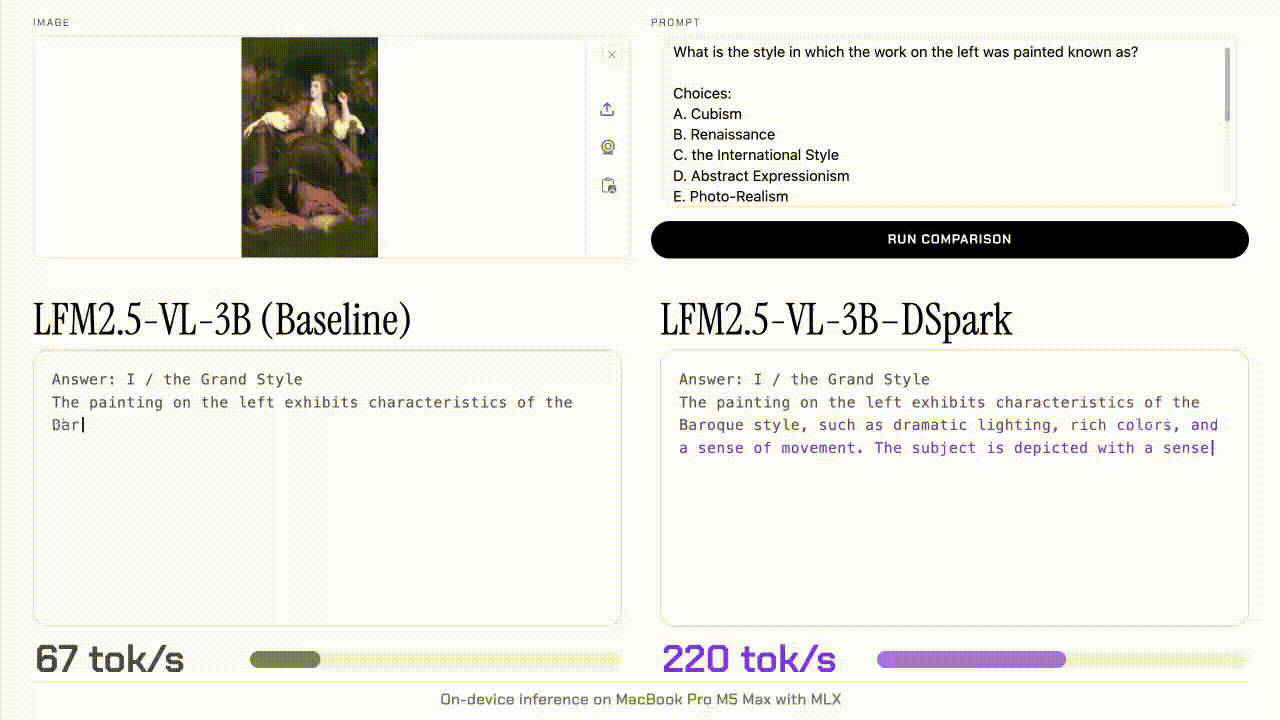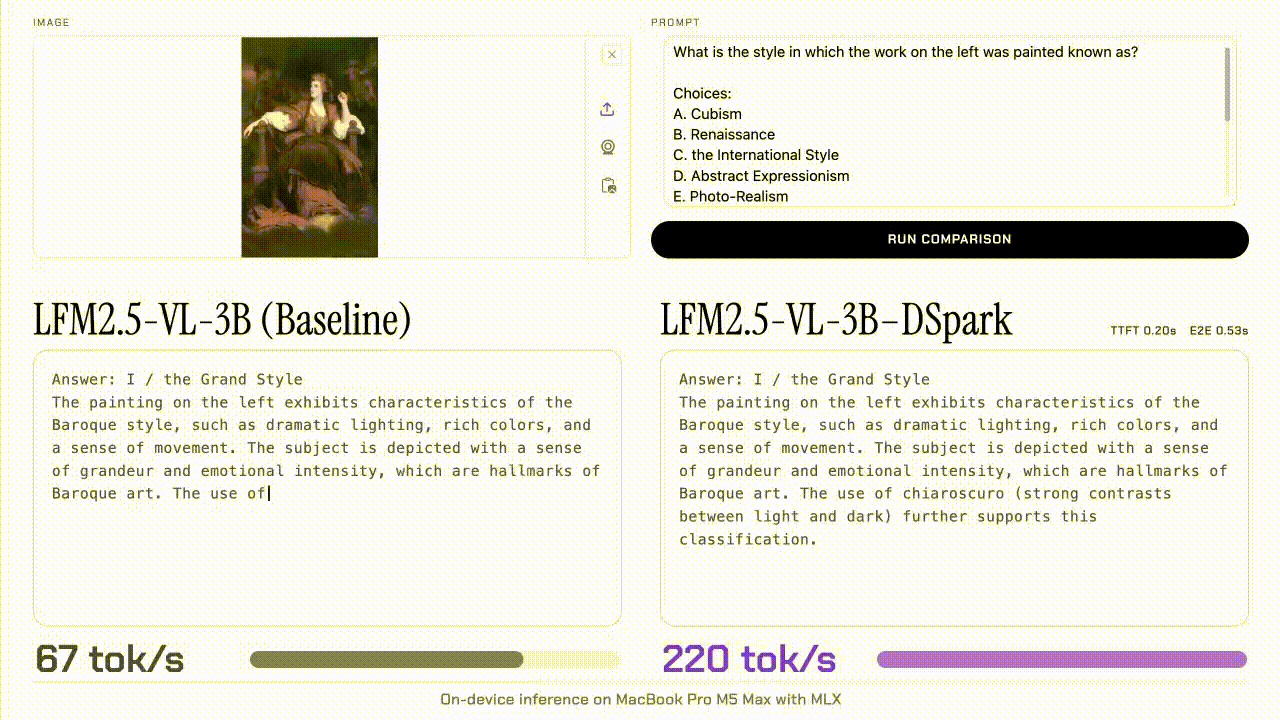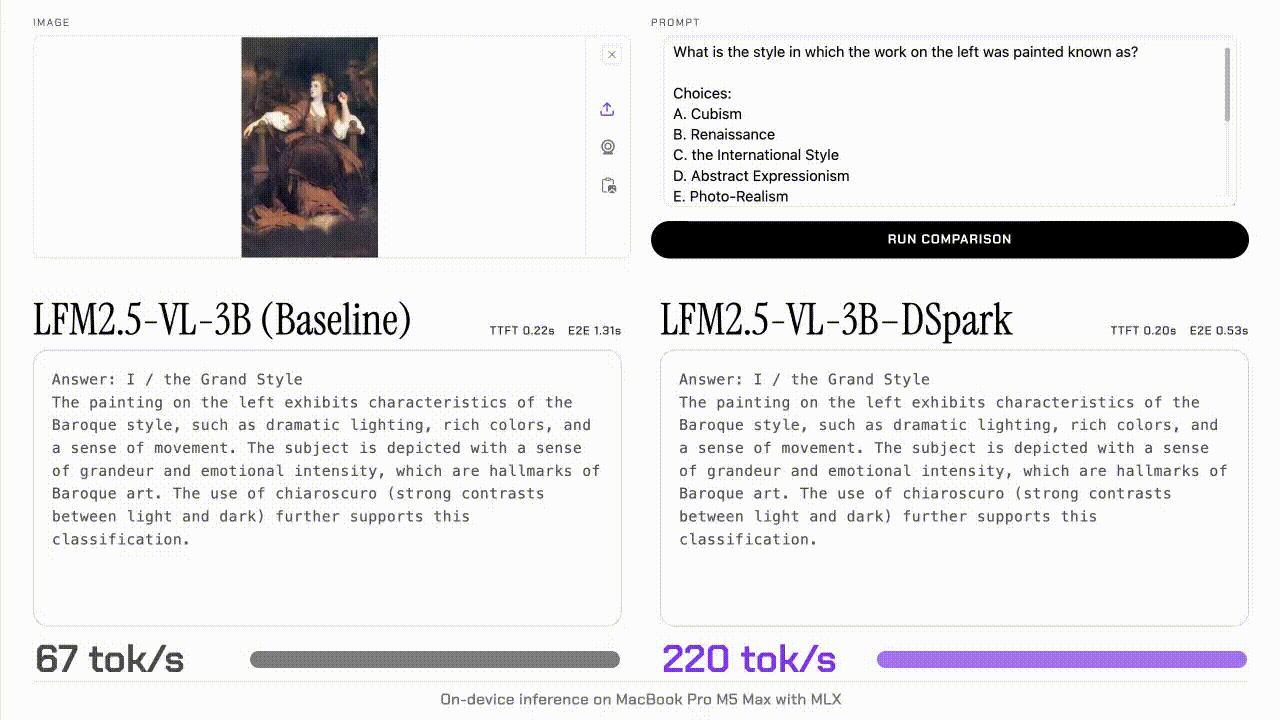
Faster inference: decode speedups up to 3.13x on device and 2.66x on an H100, with end-to-end gains up to 2.62x and 2.27x.
By xx, Yuri Khrustalev, Leonie Monigatti, Viviana MárquezHugging Face Blog
Read the full story
Originally published by Hugging Face Blog on Sep 24, 2026.
Comments
Sign in to join the discussion.