
Lobsters57 min read
Byte Language Models: Scaling, Emergent Abstractions, and Information Allocation
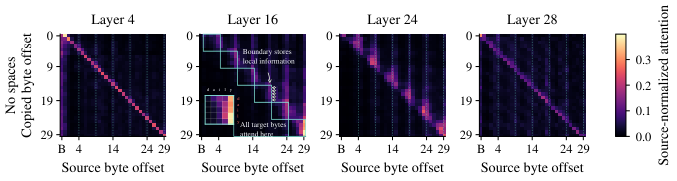
The paper challenges the assumption that language models need explicit tokenizers to be efficient demonstrating that standard flat Transformers can process raw byte sequences and actually outperform traditional subword models as parameter sizes scale.
By arxiv.org via YogthosLobsters
Read the full story
Originally published by Lobsters on Oct 10, 2026.
Comments
Sign in to join the discussion.