
PyTorch11 min read
From CUDA to MLX: How K-Search Brings Decades of Kernel Expertise to Apple Silicon
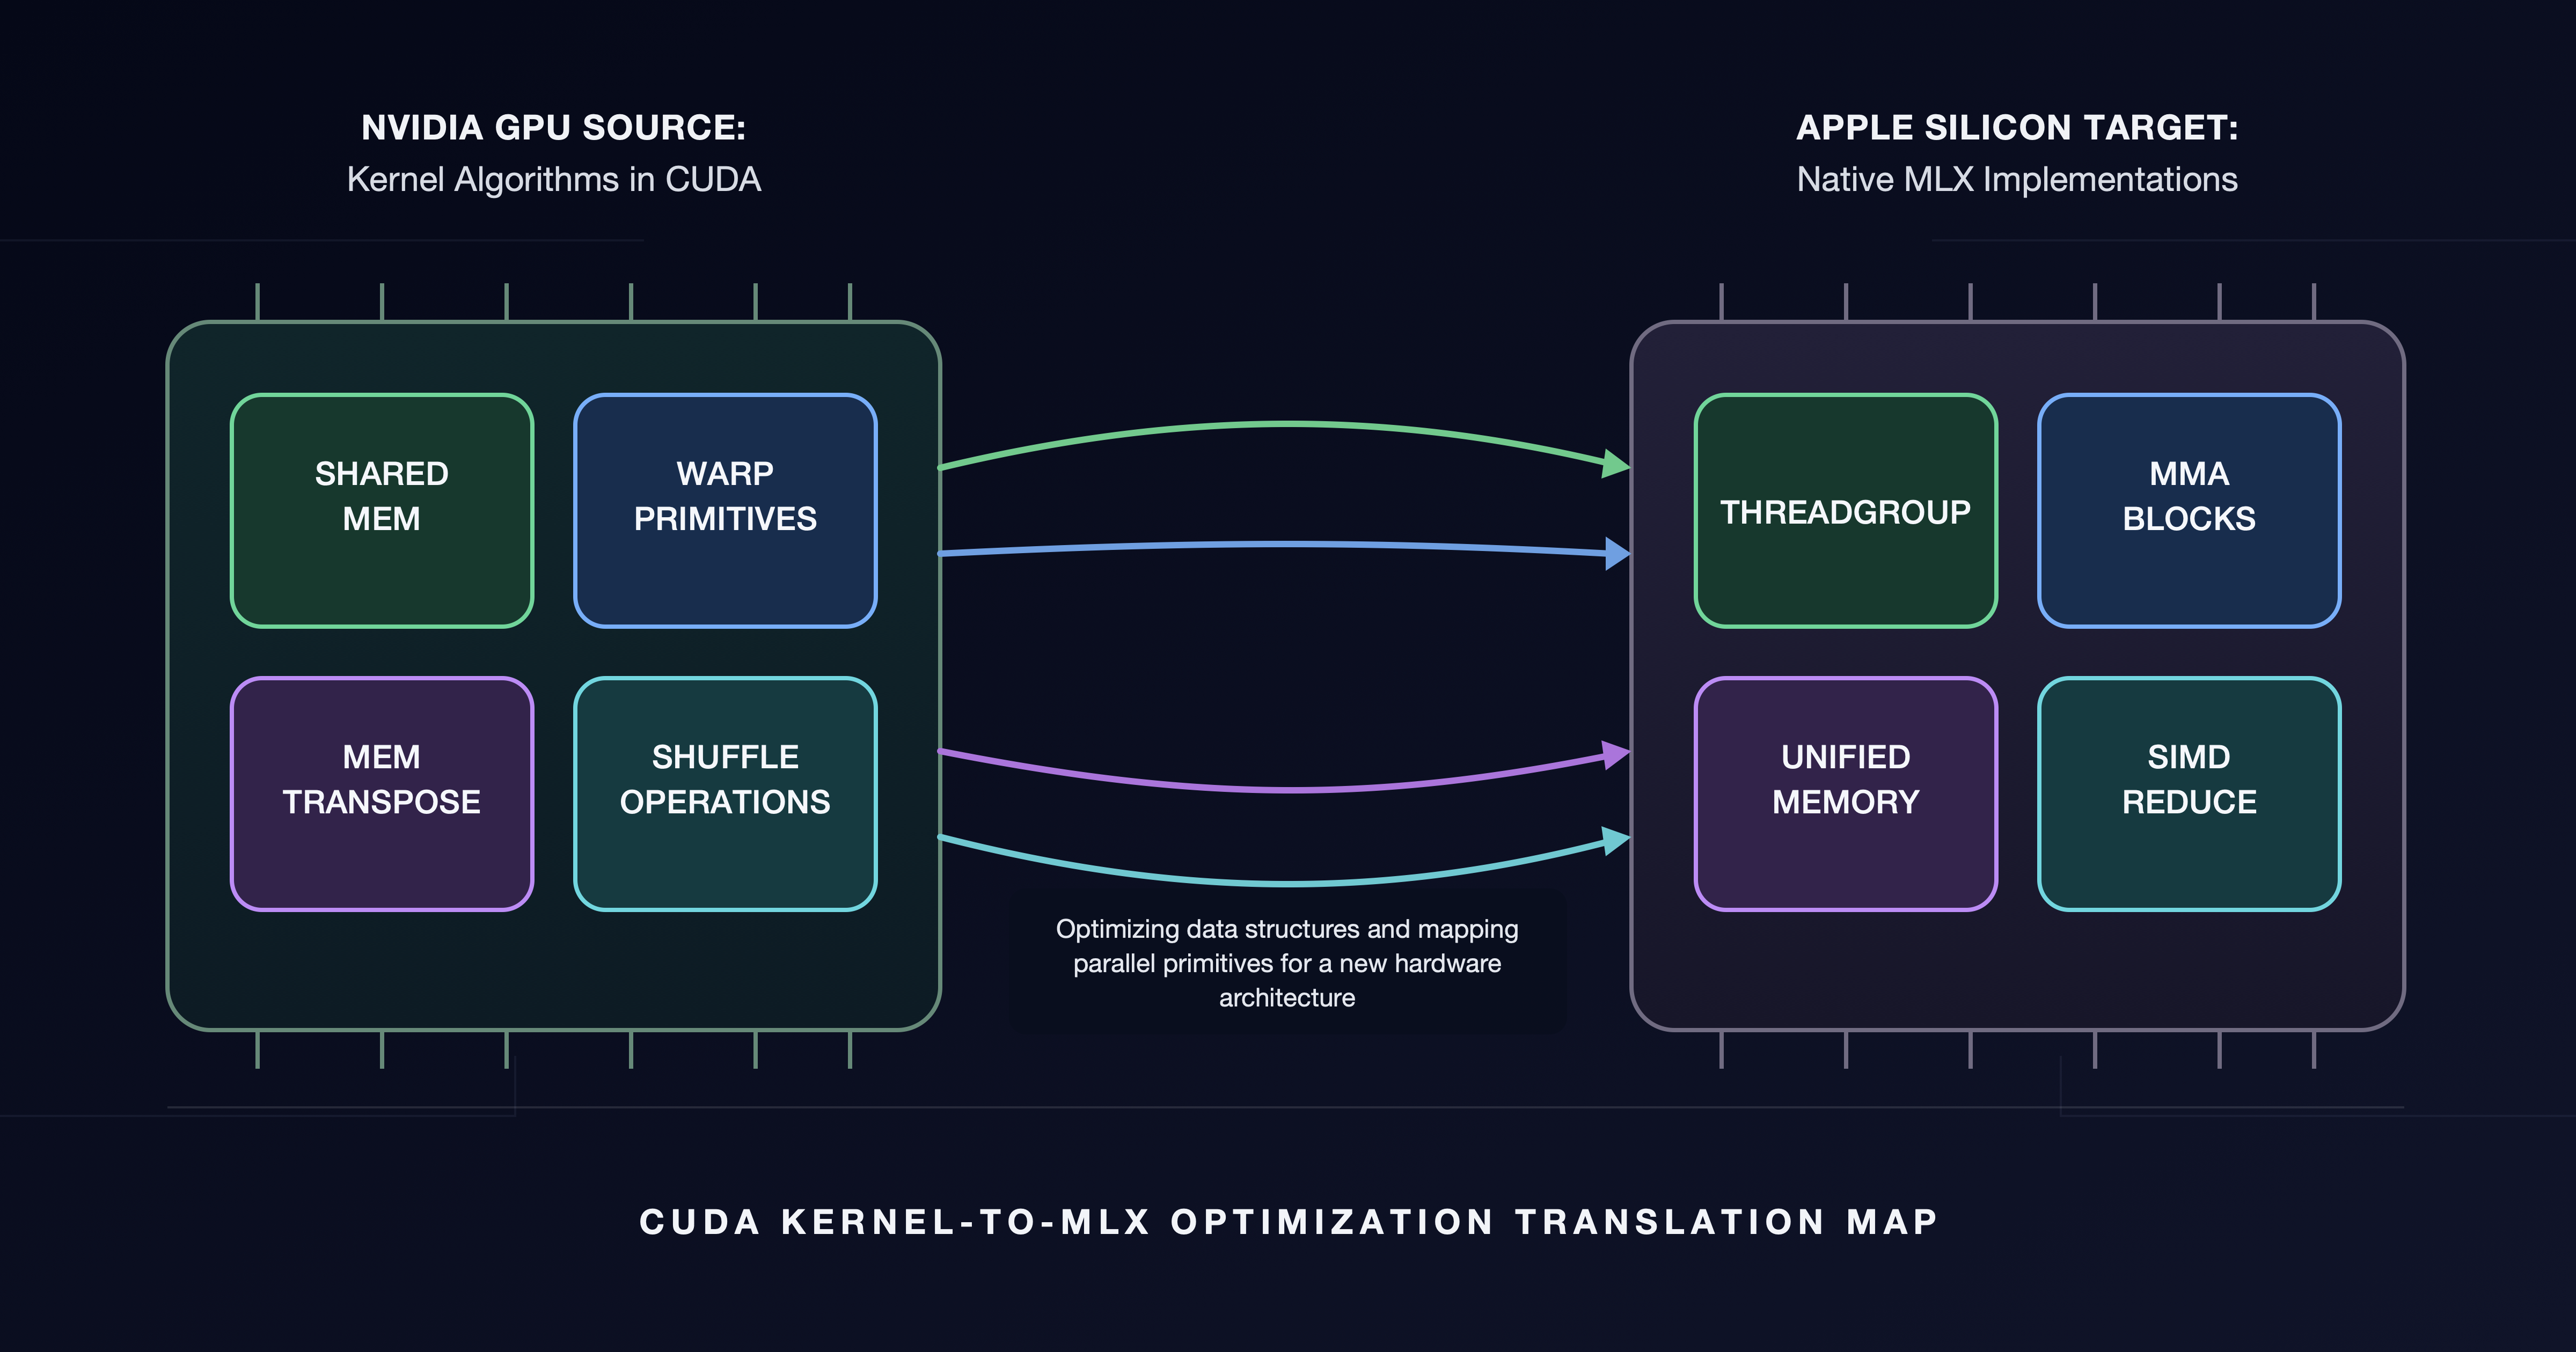
Figure 1: CUDA-to-MLX optimization translation map. CUDA optimization knowledge can be translated into architecture-native MLX strategies rather than copied instruction-for-instruction. We face a new epoch in computing.
By C.K. WolfeBerkeley AI (BAIR)
Read the full story
Originally published by Berkeley AI (BAIR) on Jul 29, 2026.
Comments
Sign in to join the discussion.