
jetbrains-ai4 min read
Junie Local became 70% faster on Mac M5
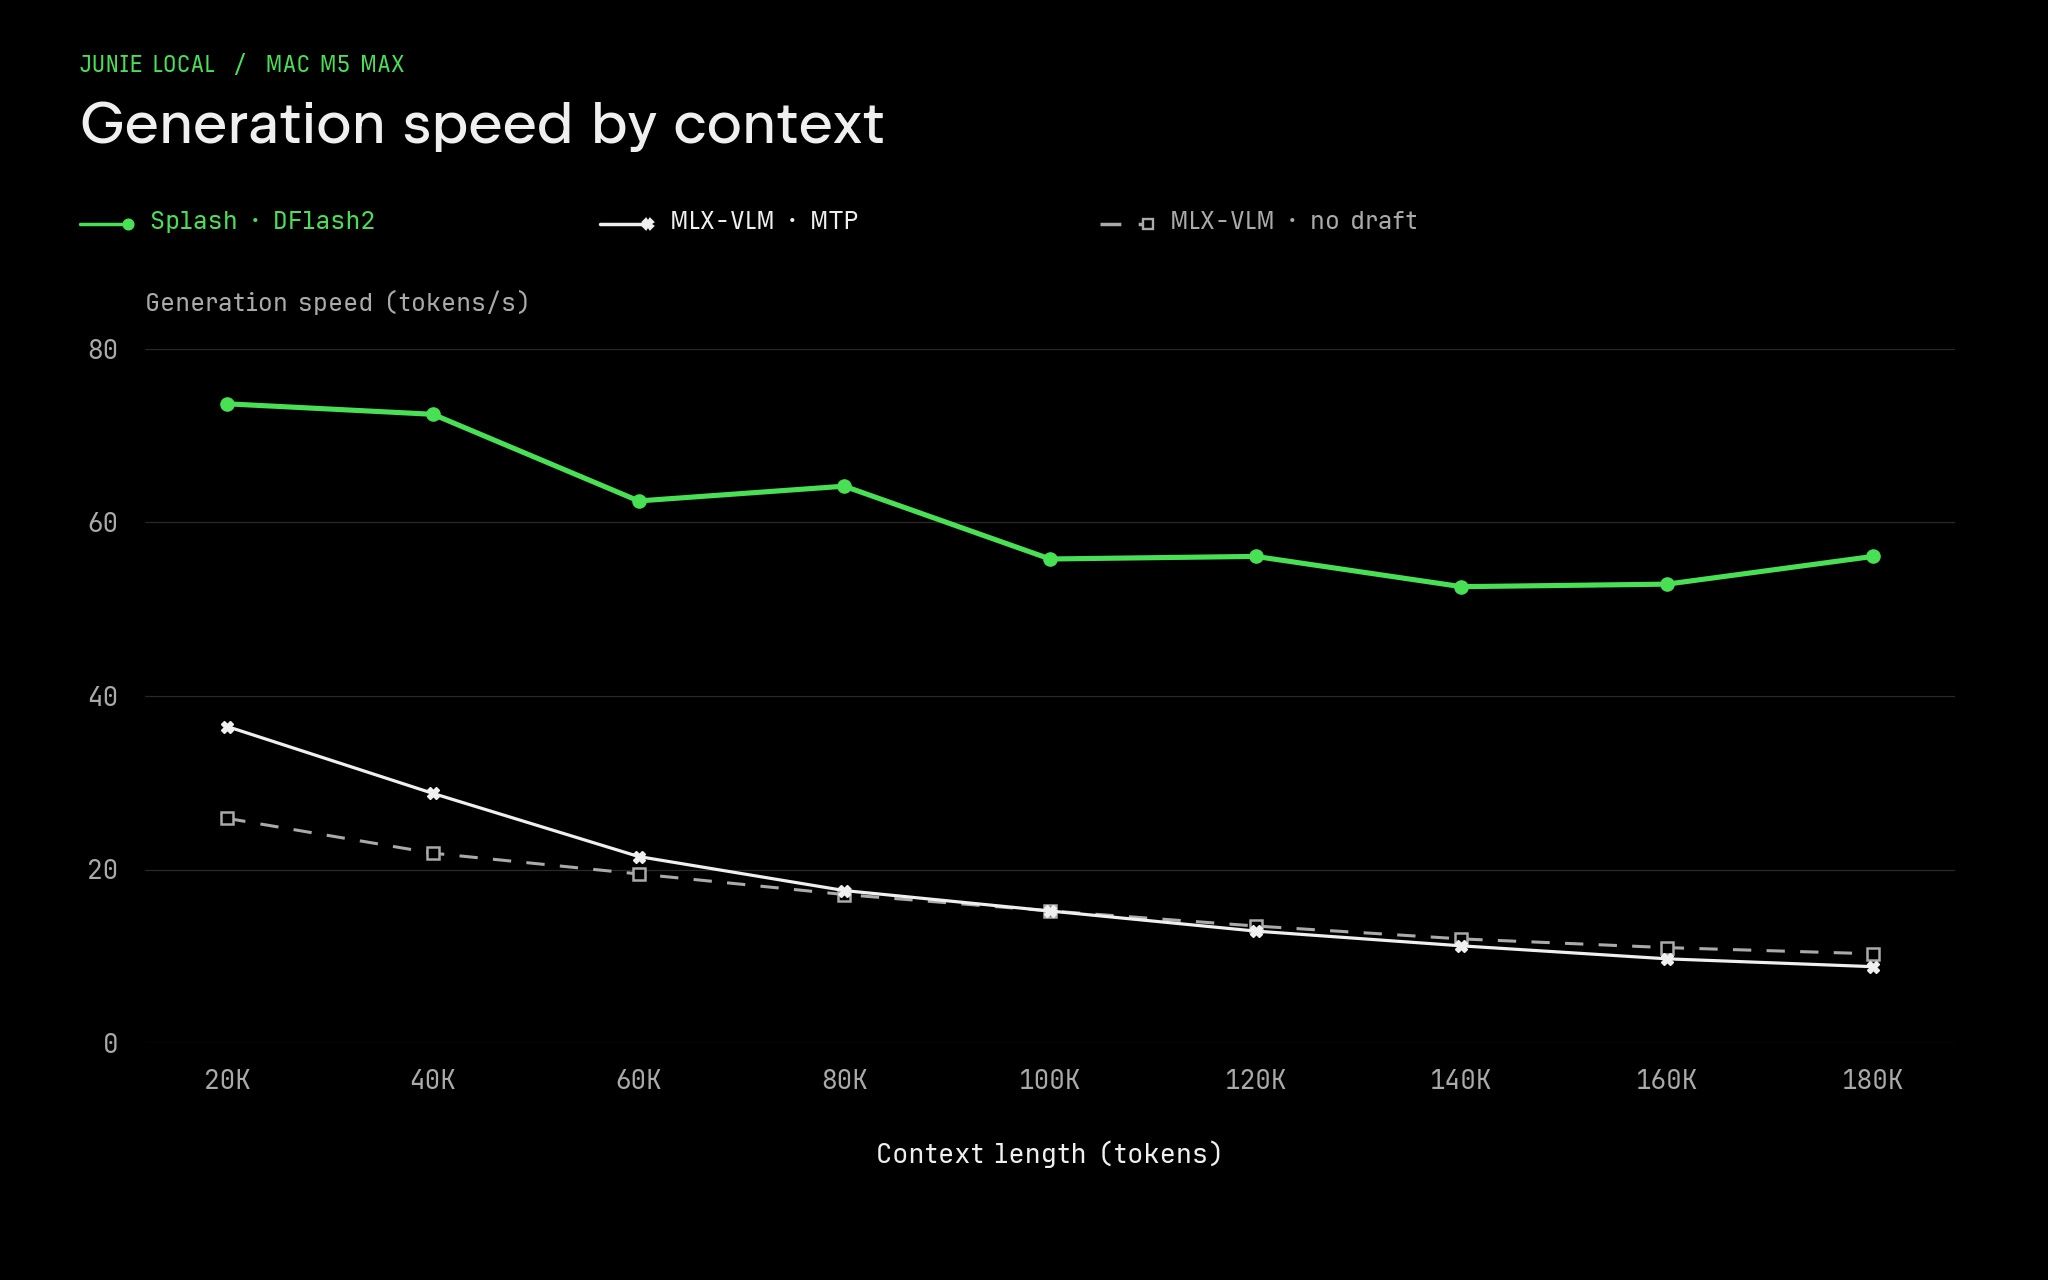
Junie Local now delivers ~70 tokens/s on M5 Max for coding tasks, up from ~40 tokens/s, with bursts up to 107 tokens/s. Two changes made this possible: the Splash inference engine and a new DFlash2 draft model. Back in August, when we first released Junie Local for Mac M5, we spent a lot of time […]


By Stanislav ErokhinJetBrains AI Blog
Read the full story
Originally published by JetBrains AI Blog on Oct 28, 2026.
Comments
Sign in to join the discussion.