
Linus Torvalds is using AI to develop Linux kernel code now
The move is a turning point in the developer’s relationship with AI and Linux.
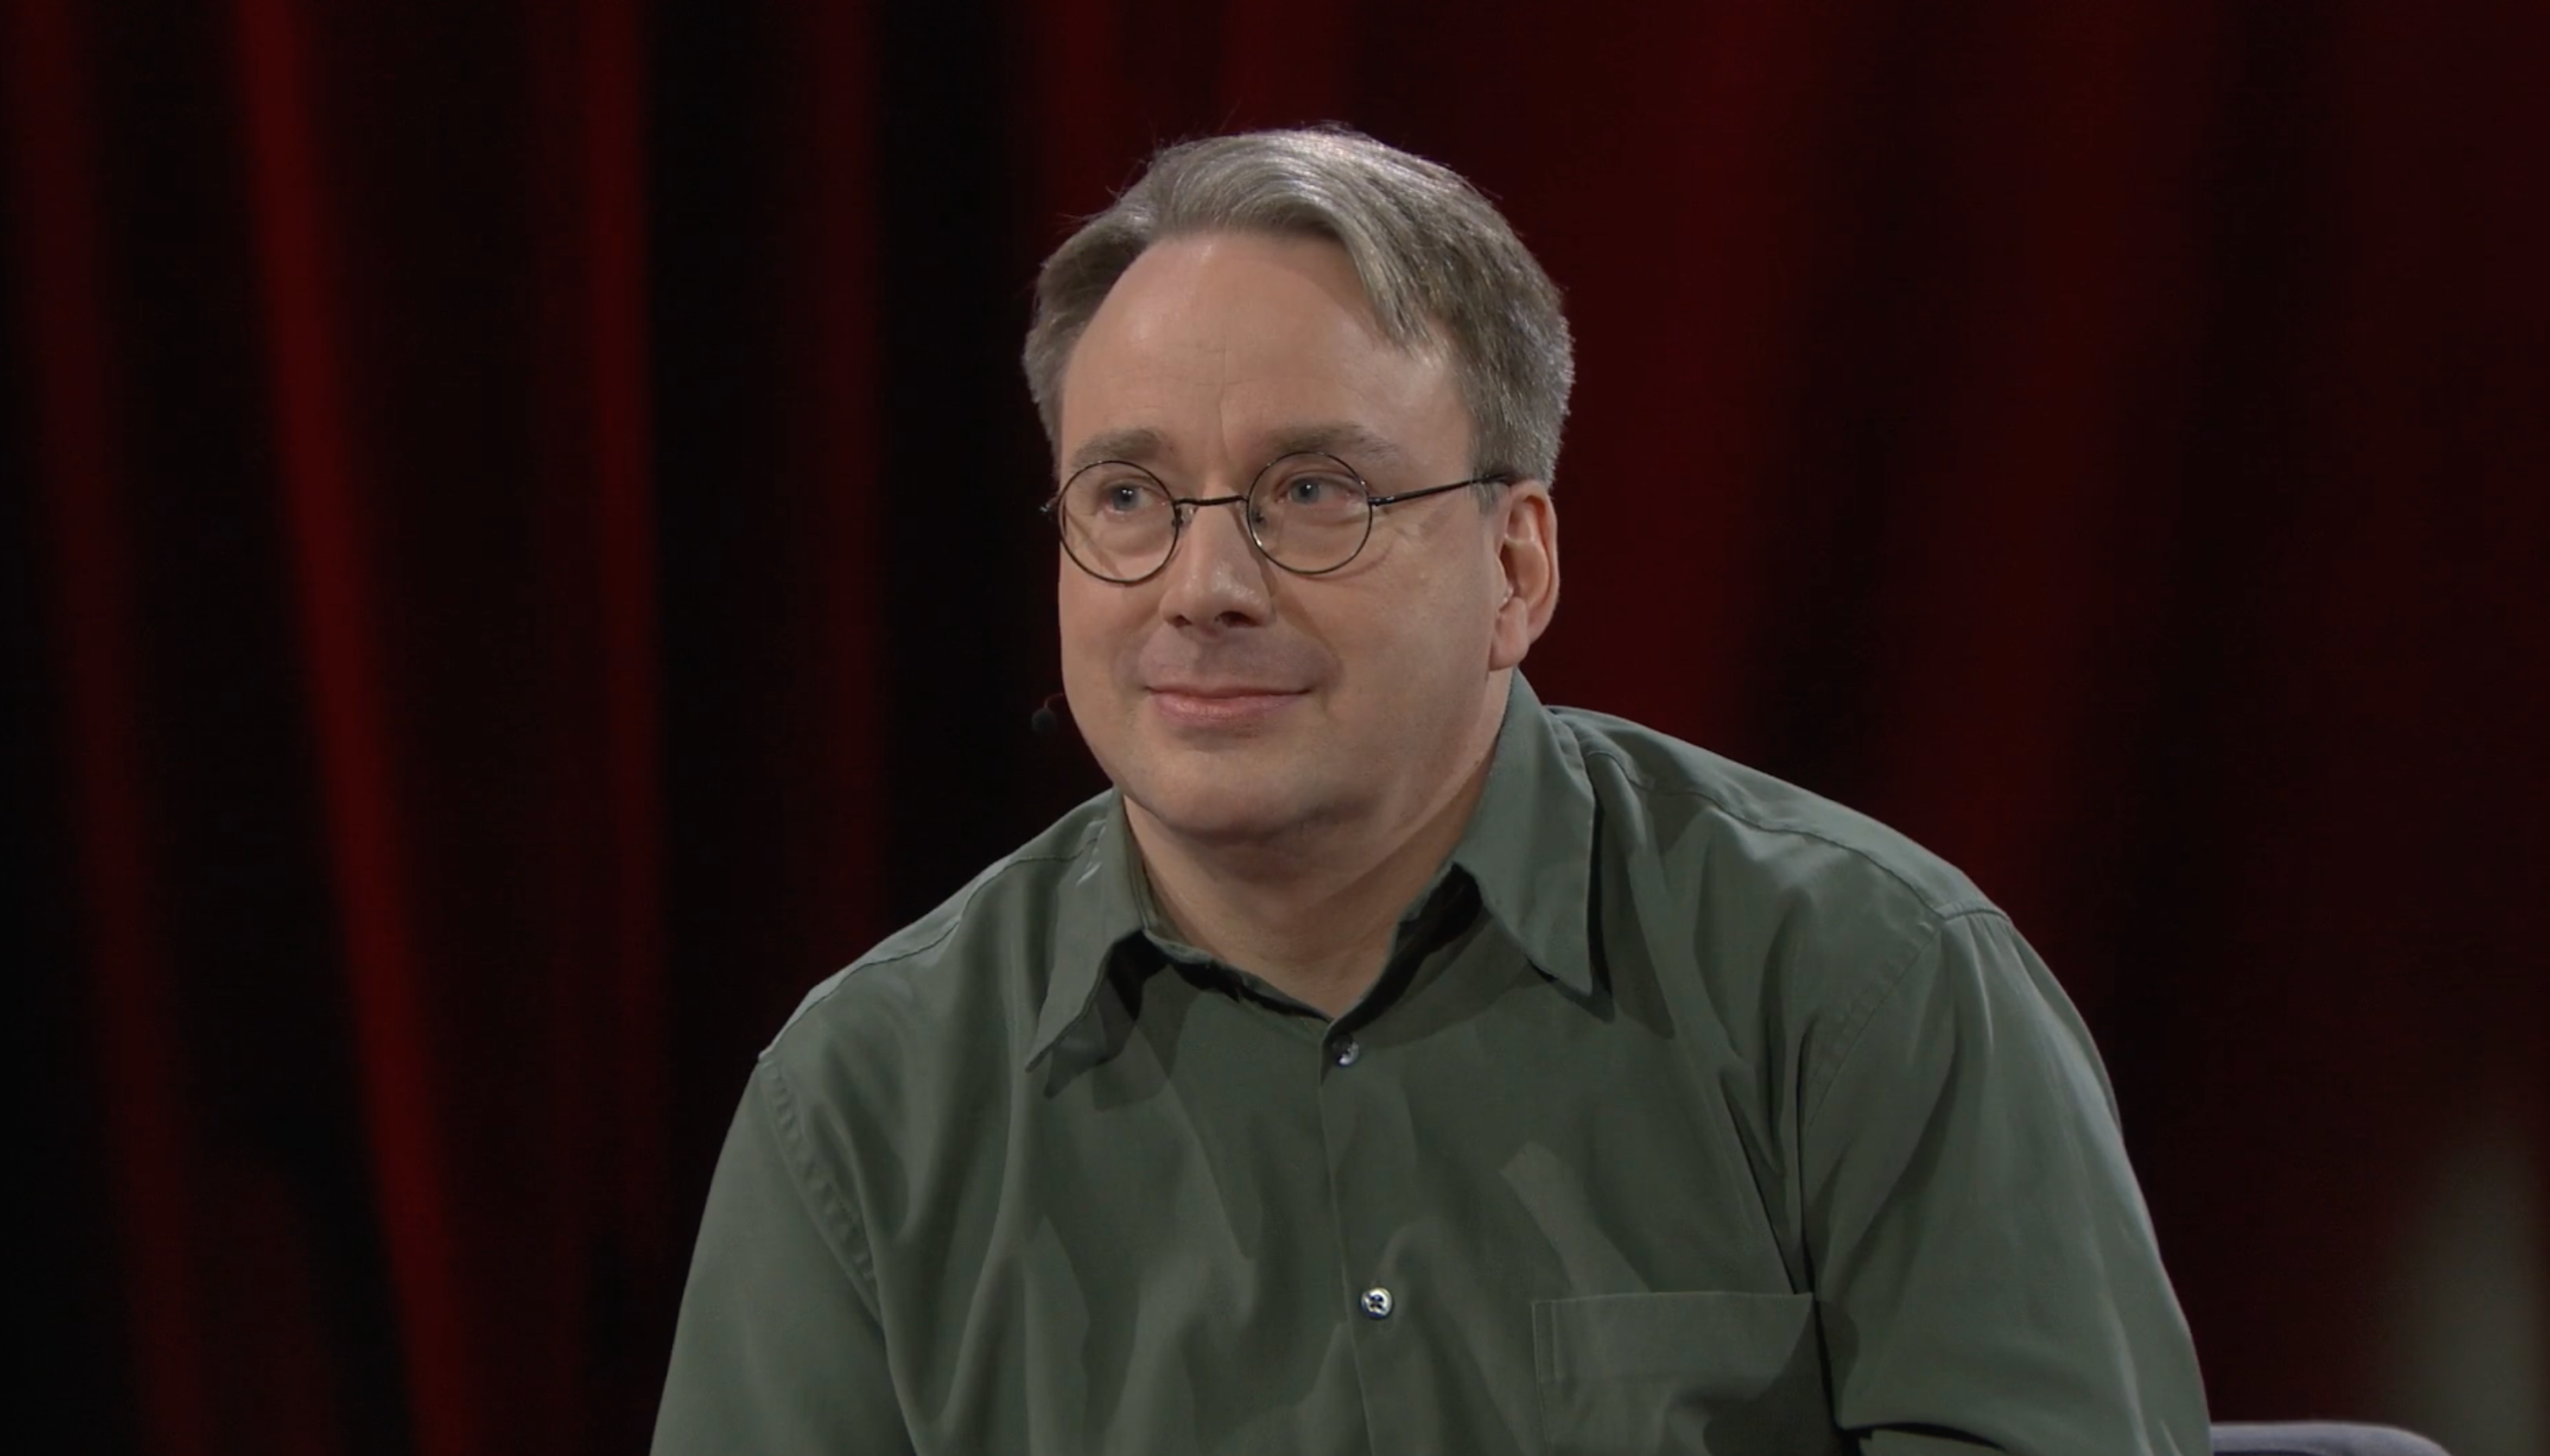
Linus Torvalds, the creator of the Linux kernel, has begun using AI to develop kernel code, marking a significant shift in his approach to artificial intelligence tools.
What happened
Linus Torvalds released AI-generated patches for the Linux kernel to address a memory cache slowdown issue. The code, developed with Anthropic's Claude Code, aims to optimize small-read workloads by modifying how the kernel manages page cache references. While the patches show performance improvements, they introduce unresolved trade-offs in memory reclamation and regression issues.
Why it matters
This development highlights AI's growing role in critical system-level programming. As the Linux kernel maintains 1.5 billion lines of code, Torvalds' adoption of AI tools signals a potential shift in how complex software projects leverage machine learning for code generation and optimization.
- AI is now being used for kernel-level code development by leading engineers
- Performance gains in specific workloads require trade-offs in memory management
- Torvalds' journey reflects broader industry adoption of AI as a development tool
The bigger picture
The experiment demonstrates AI's potential for solving complex performance issues in operating systems, while also highlighting the need for careful validation of AI-generated code in critical infrastructure.
Linus Torvalds' use of AI to develop Linux kernel patches represents a pivotal moment in the integration of machine learning tools into critical software development processes.
Technical details
- Page cache contention in multi-core systems due to atomic reference count updates
- Read-Copy-Update (RCU) grace periods for deferred memory reclamation
- Patch series noref-filemap-read-with-llm
- Hit in Modified (HITM) cache line metrics
- Pread() system call workload optimization
FAQ
What specific problem did the AI-generated patches address?
The patches resolved a memory cache bottleneck caused by contention in Linux's page cache when multiple threads perform small reads from the same file.
How did the AI-assisted code improve performance?
By deferring memory reclamation until RCU grace periods, the code reduced shared cache line contention, resulting in 3x higher throughput for multi-threaded small-read workloads.
What are the limitations of the AI-generated patches?
The approach introduces unresolved memory reclamation delays and a regression when reading unmapped user pages, requiring further validation before mainline integration.
This summary and analysis were generated with AI from the original article and may contain errors. Read the original for the full story.
Read the full story
Originally published by ZDNet on Oct 13, 2026.
Comments
Sign in to join the discussion.