
machine learning2 min read
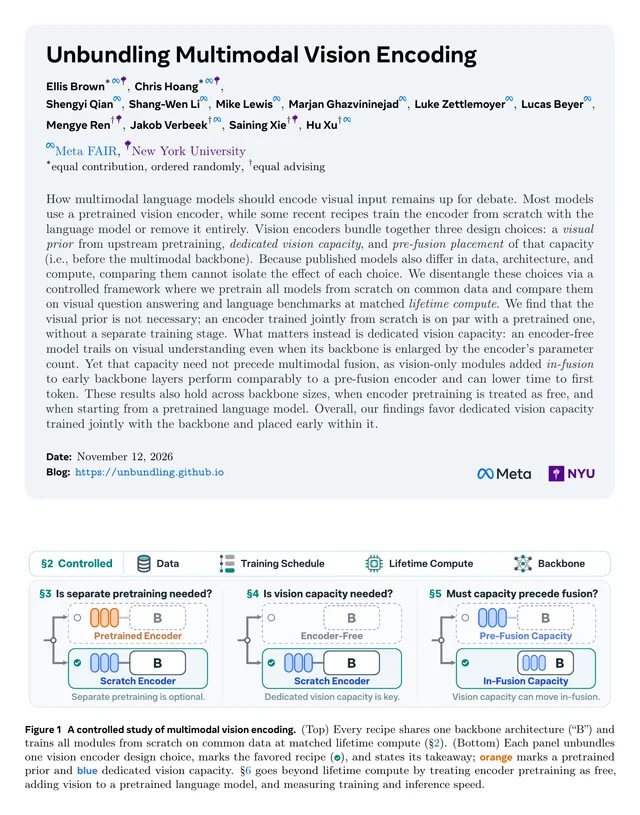
[Meta FAIR + NYU] Unbundling Multimodal Vision Encoding: training 200+ MLLMs to find encoder pretraining is optional but vision-only parameters are not [R]
X threads (with videos!): https://x.com/choang333/status/2121335484236386574 https://x.com/_ellisbrown/status/2121335477244428419 Paper: https://www.alphaxiv.org/abs/2611.17334 Blog and FAQ: https://unbundling.github.io Labs disagree on vision encoders right now.


By /u/trungh98Reddit - r/ML
Read the full story
Originally published by Reddit - r/ML on Nov 15, 2026.
Comments
Sign in to join the discussion.