
Nonobench: an open benchmark of 49 LLMs on nonogram puzzles, public and open source [P]
Nonobench measures how well LLMs solve nonograms (picross). Each model gets the row and column clues once and returns the full grid. No tools, one attempt per puzzle. Method: - Standard mode: 30 puzzles from 5x5 to 15x15 (from the Nonograms dataset by Moyà-Alcover, CC BY 4.0).
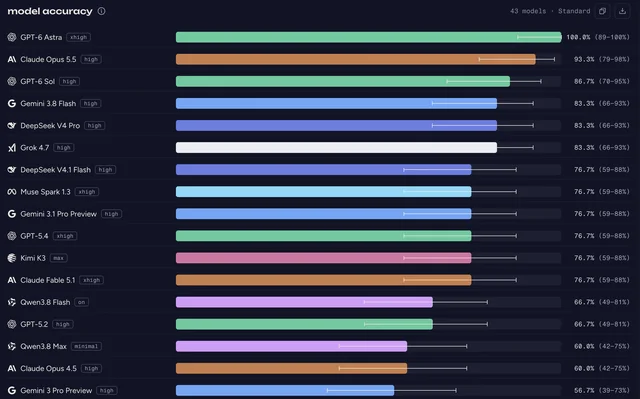
Nonobench is an open benchmark that evaluates the performance of 49 large language models (LLMs) in solving nonogram puzzles, also known as picross puzzles. The benchmark provides insights into how well these models can reason and solve complex logic puzzles.
What happened
Nonobench is an open benchmark that evaluates the performance of 49 large language models (LLMs) in solving nonogram puzzles. The benchmark includes two modes: Standard mode with 30 puzzles ranging from 5x5 to 15x15, and Hard mode with 10 random 20x20 puzzles. Each model receives the row and column clues once and returns the full grid without using tools or multiple attempts. The results show that solve rates drop significantly with increasing puzzle complexity, with GPT-6 Astra performing best in Standard mode and Claude Opus 5.5 showing strong performance in Hard mode.
Why it matters
The benchmark is important for AI developers and researchers as it provides a standardized way to evaluate the reasoning and problem-solving capabilities of LLMs. It highlights the challenges these models face in solving complex logic puzzles, which can inform the development of more advanced reasoning capabilities in future models.
- Nonobench is a valuable benchmark for evaluating the reasoning and problem-solving capabilities of LLMs.
- The benchmark highlights the limitations of LLMs in solving complex logic puzzles.
- GPT-6 Astra and Claude Opus 5.5 show strong performance in different modes of the benchmark.
- The benchmark provides insights into the challenges faced by LLMs in solving nonogram puzzles.
- The results can inform the development of more advanced reasoning capabilities in future models.
The bigger picture
The benchmark has practical implications for the development of LLMs, as it highlights the need for improved reasoning and problem-solving capabilities. It also provides a resource for researchers to compare and evaluate the performance of different models in solving complex logic puzzles.
Nonobench is an open benchmark that evaluates the performance of 49 LLMs in solving nonogram puzzles. The benchmark provides insights into the reasoning and problem-solving capabilities of these models, highlighting their strengths and limitations in solving complex logic puzzles.
Technical details
- Nonobench uses the Nonograms dataset by Moyà-Alcover, CC BY 4.0.
- The benchmark includes 130 variants across different reasoning effort levels.
- Results are run through OpenRouter and pinned to each lab's own endpoint where possible.
- Hard mode puzzles are checked to have a single solution, with five puzzles requiring more than line logic alone.
- Answers in Hard mode are provided as an array of 20 row strings rather than a single string.
FAQ
What is Nonobench?
Nonobench is an open benchmark that evaluates the performance of 49 large language models (LLMs) in solving nonogram puzzles, also known as picross puzzles.
What are the two modes of the benchmark?
The benchmark includes two modes: Standard mode with 30 puzzles ranging from 5x5 to 15x15, and Hard mode with 10 random 20x20 puzzles.
How are the puzzles solved in the benchmark?
Each model receives the row and column clues once and returns the full grid without using tools or multiple attempts.
Which models performed best in the benchmark?
GPT-6 Astra solved all 30 Standard puzzles, while Claude Opus 5.5 solved 8 of 10 in Hard mode.
What are the limitations of the benchmark?
The benchmark has limitations, such as one attempt per puzzle, which results in noisy single results, and the use of 95% intervals to show variability.
This summary and analysis were generated with AI from the original article and may contain errors. Read the original for the full story.
Read the full story
Originally published by Reddit - r/ML on Oct 4, 2026.
Comments
Sign in to join the discussion.