
TorchNeuron9 min read
Profiling TorchNeuron (Part 1): System-level profiling on AWS Trainium.
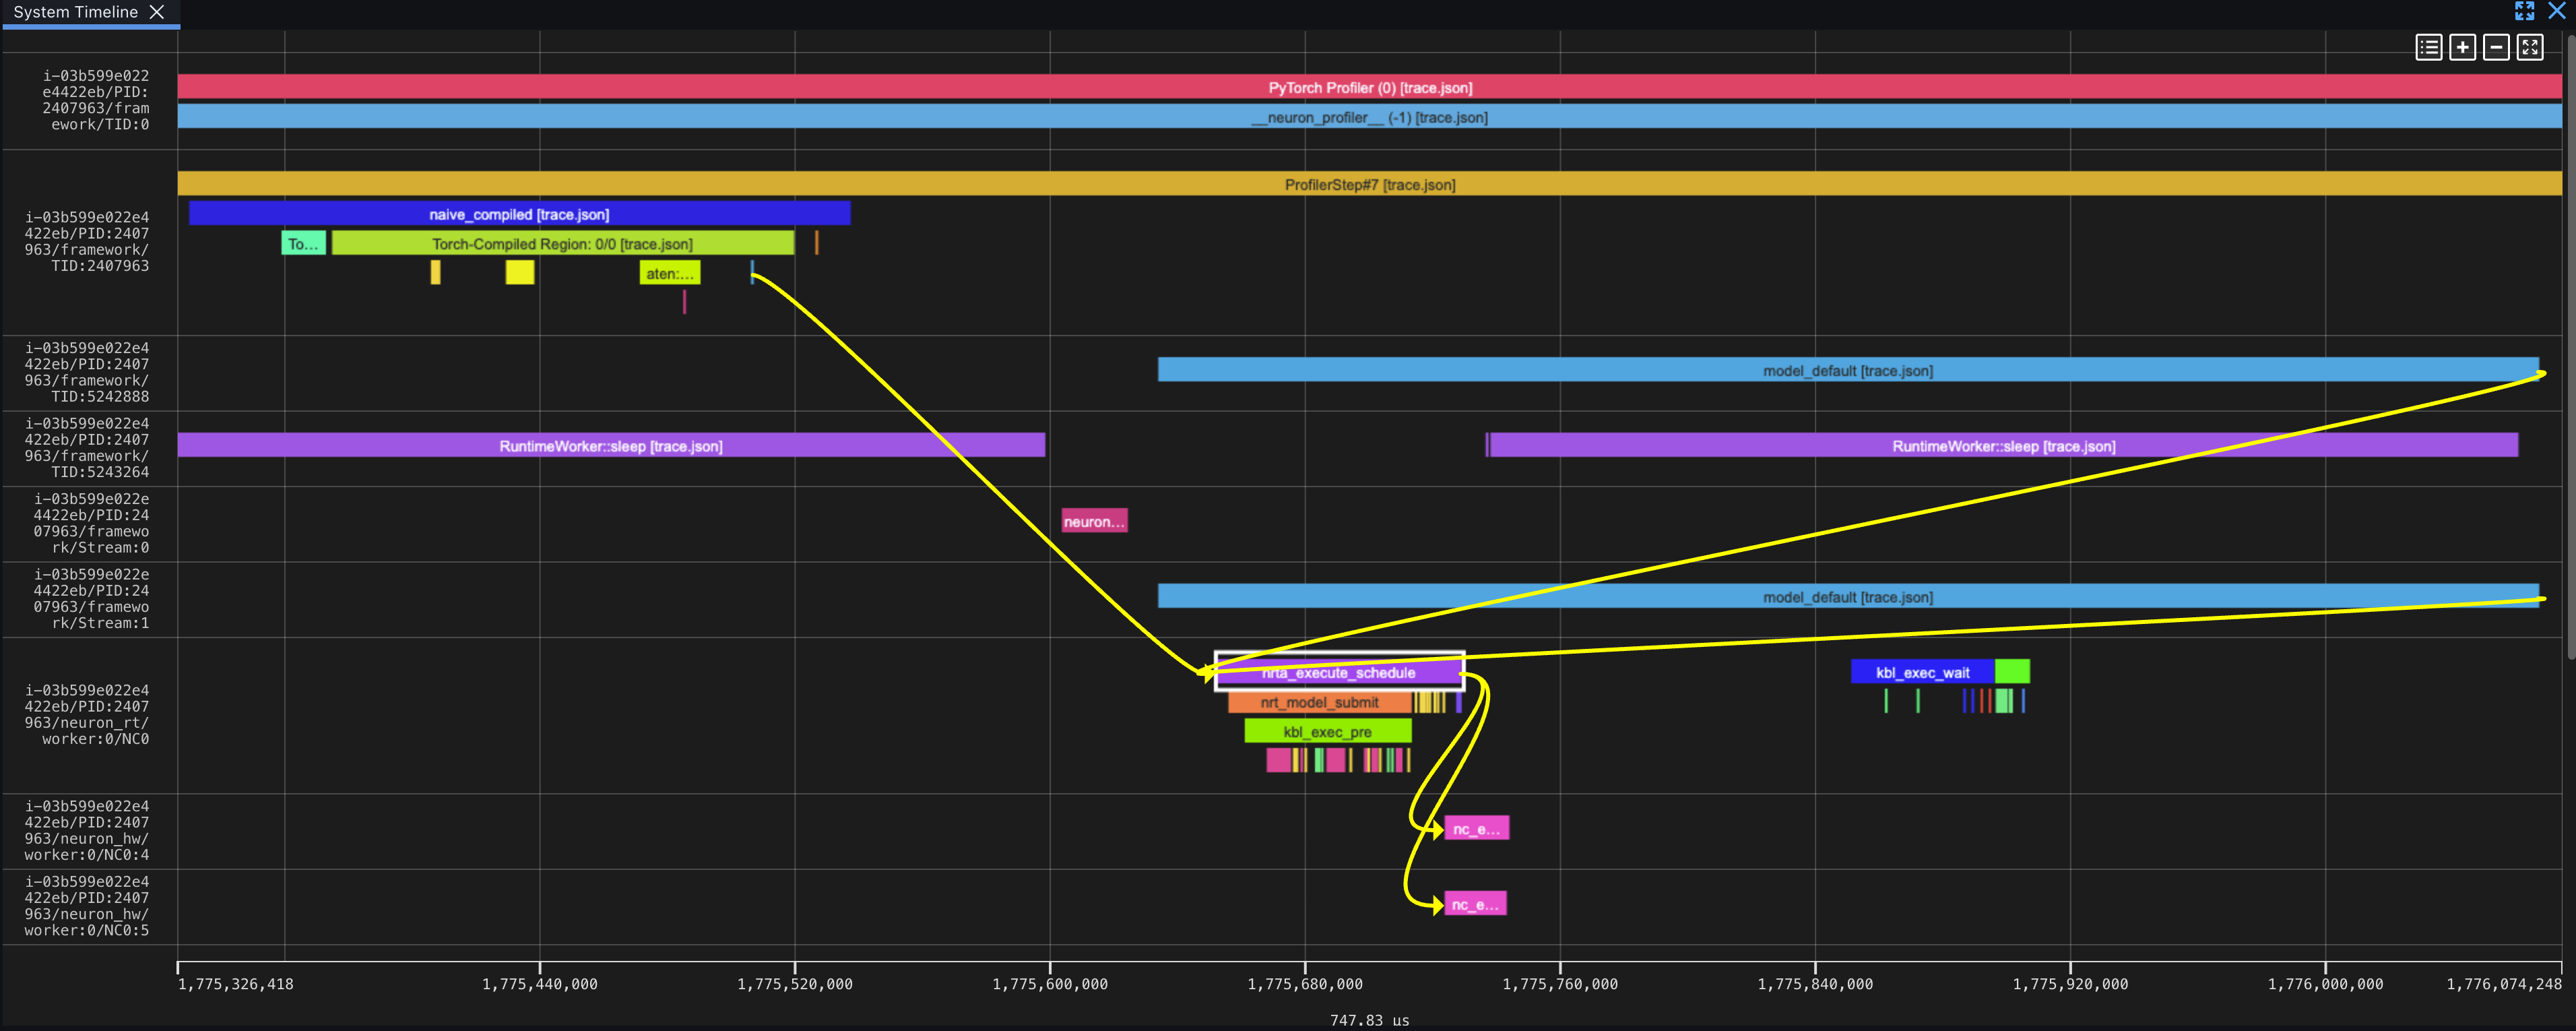
Many ML practitioners have some intuition about how to make models run fast, but fewer know how to analyze why a model is slow. In Part 1 of this series, you will learn how to systematically analyze inference performance and identify where the time is spent.


By Josh LongeneckerHugging Face Blog
Read the full story
Originally published by Hugging Face Blog on Oct 21, 2026.
Comments
Sign in to join the discussion.