
LessWrong26 min read
Projection sampling preserves capabilities but diminishes gains from alignment fine-tuning
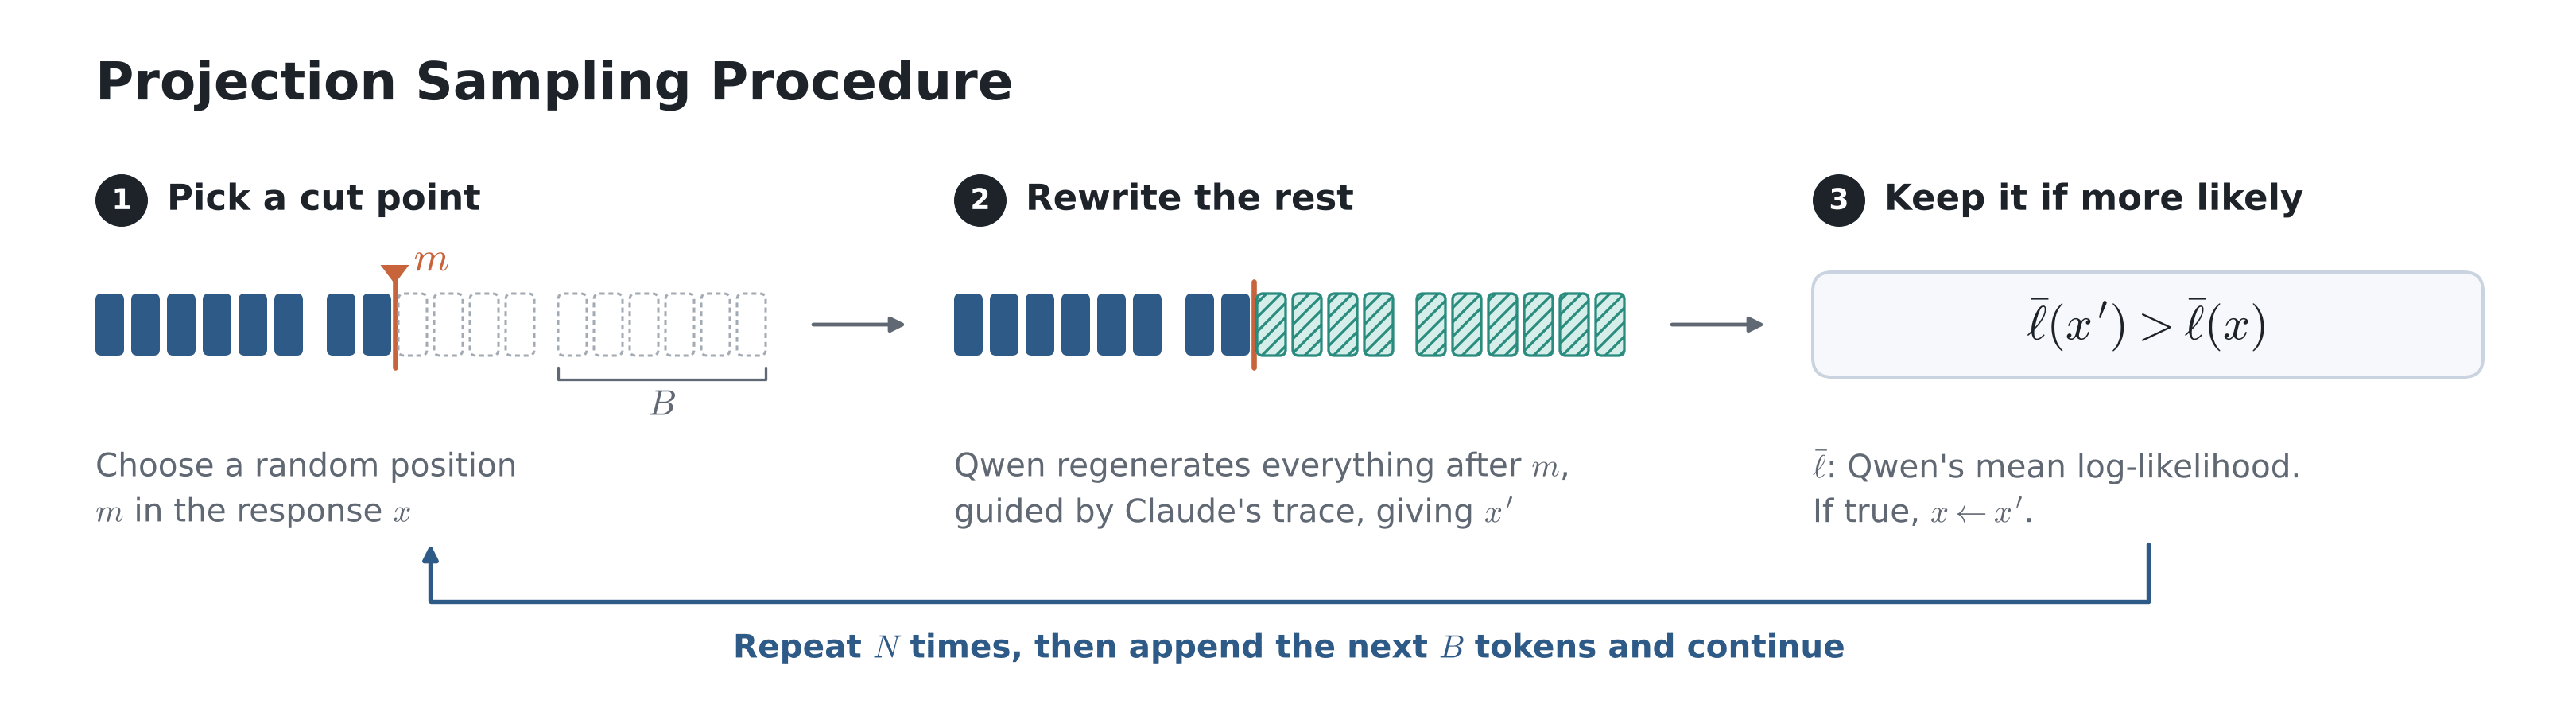
TLDRFine-tuning models on alignment reasoning from stronger models can improve safety, but at a substantial cost to general capabilities. Previous work has shown that replay, mixing the alignment traces with the student model's own responses to generic instructions unrelated to the task, can…
By Matthew NguyenLessWrong
Read the full story
Originally published by LessWrong on Oct 16, 2026.
Comments
Sign in to join the discussion.