
hugging face11 min read
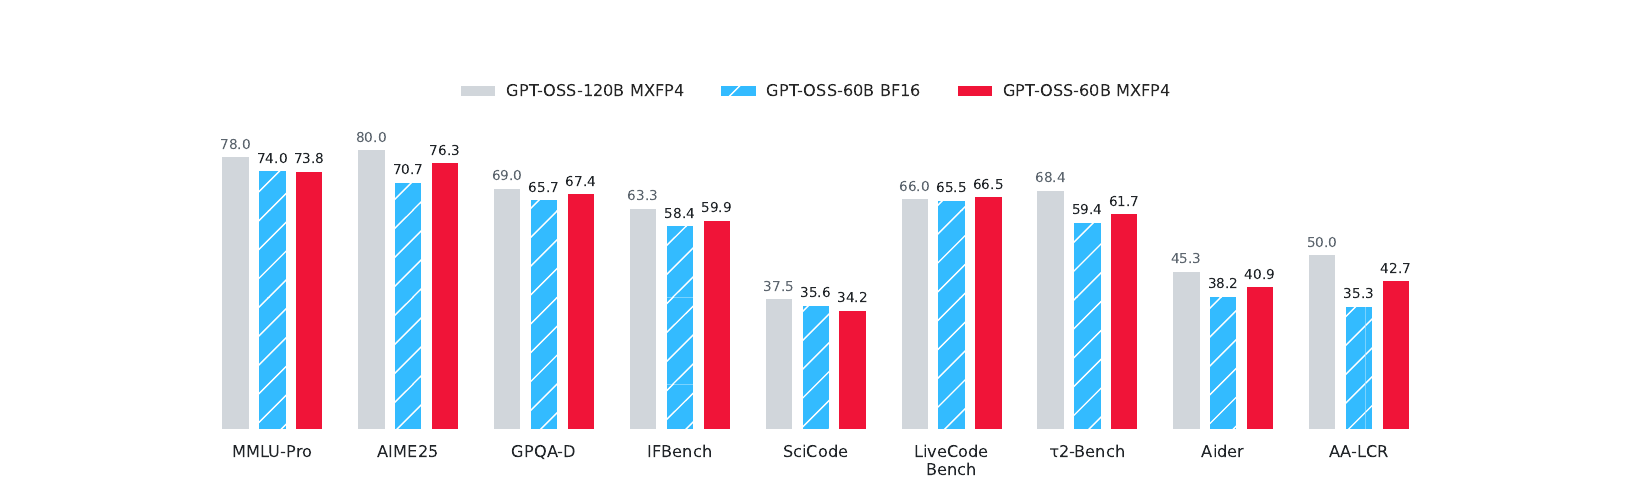
Quantization-Aware Healing: a compressed, 4-bit model that outperforms its full-precision original
Our latest paper, Quantization-Aware Healing: A Practical Recipe for Recovering Compressed, 4-Bit LLMs, asks a question that the field has mostly left open: once a model has already been through structural compression, not just quantization, how well does that recovery step actually work, and what…
By Antonio Tiene, Iker García-Ferrero, Ali Hashemi, Bakbergen RyskulovHugging Face Blog
Read the full story
Originally published by Hugging Face Blog on Aug 25, 2026.
Comments
Sign in to join the discussion.