
Synthetic Data for Fine-Tuning LLM Agents: Real Tradeoffs and Practical Tips
Fine-tuning LLM agents needs more than just text. Synthetic data helps you build robust, multi-turn interaction datasets without the cost or risk of real user data.
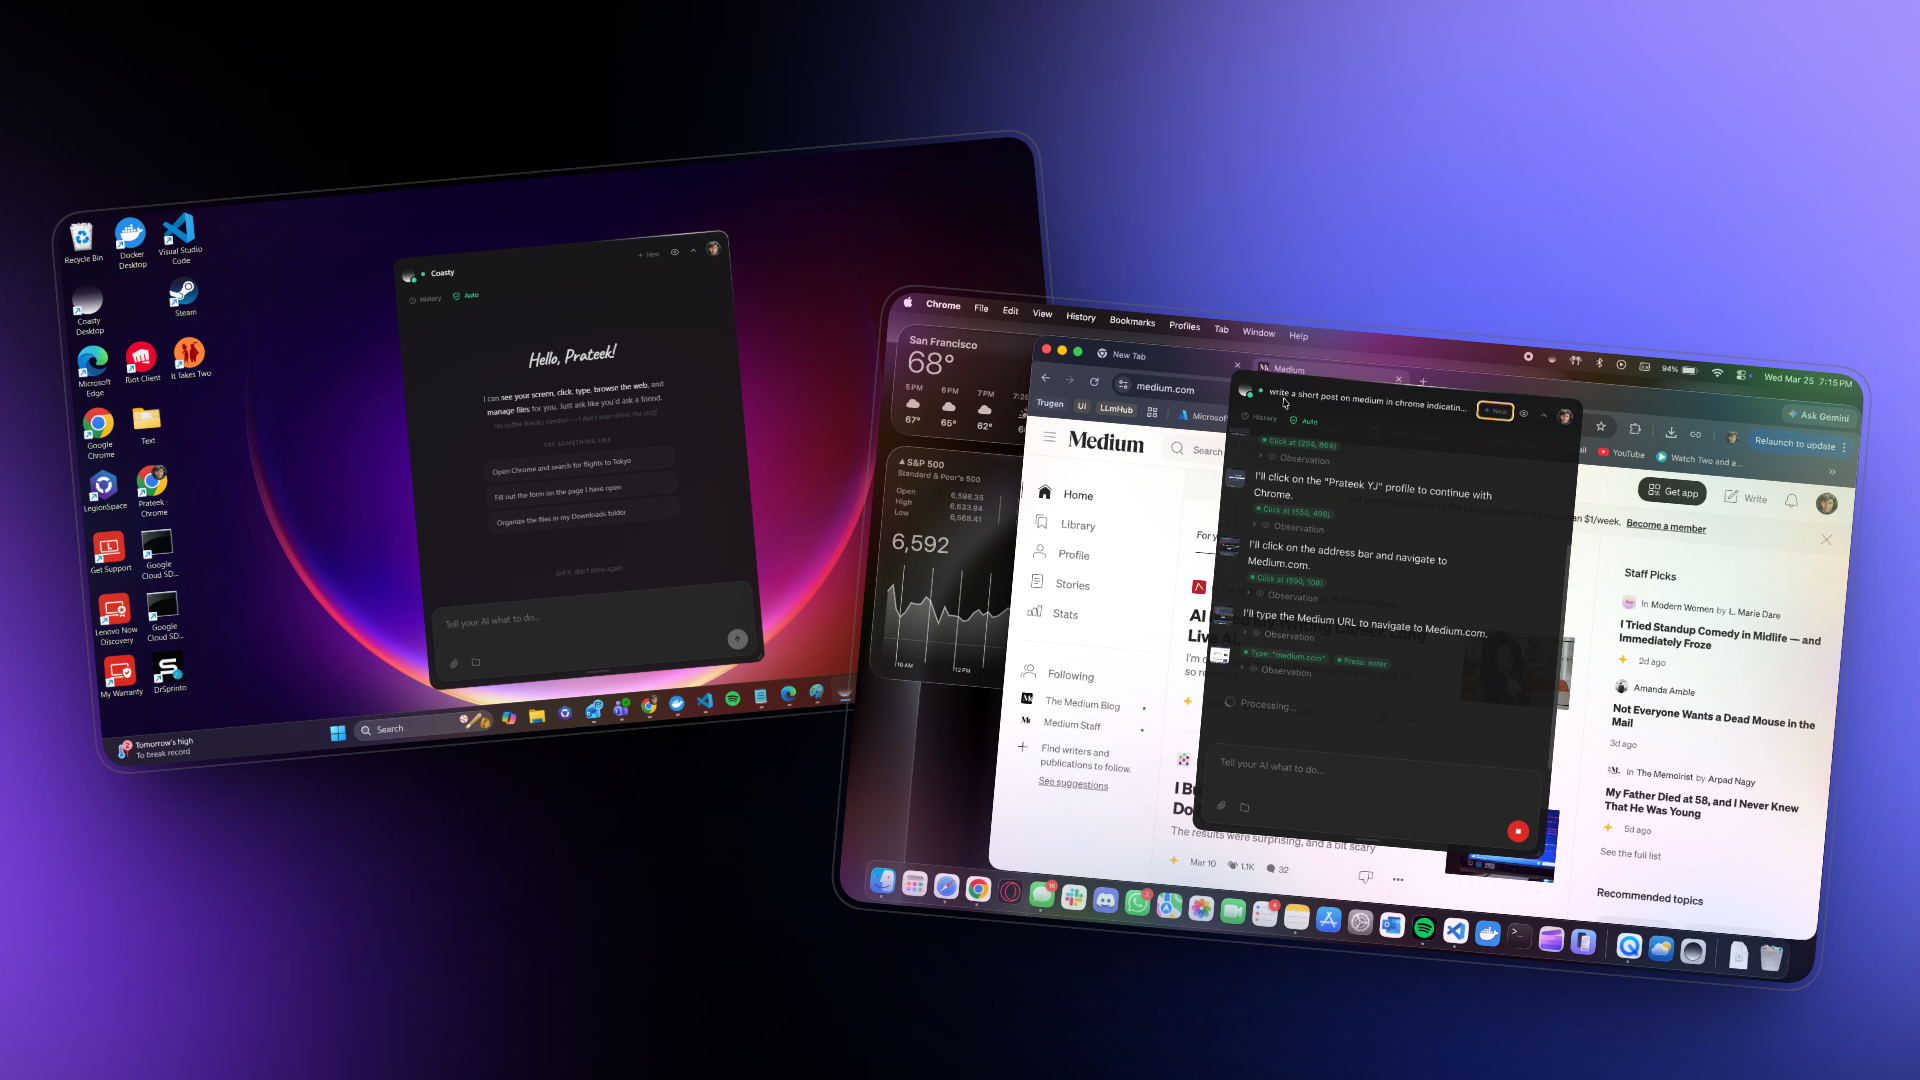
This article explores the use of synthetic data for fine-tuning large language model (LLM) agents, discussing its benefits, trade-offs, and practical implementation strategies.
What happened
The article explains how synthetic data can replace or supplement real user interaction data for training LLM agents, citing benchmarks showing synthetic trajectories achieving 93% accuracy in reasoning tasks. It outlines practical considerations for implementation and describes Coasty's role in generating synthetic datasets.
Why it matters
Synthetic data reduces reliance on costly, incomplete, or privacy-sensitive real-world data while enabling controlled experimentation. It helps build robust agents capable of handling complex, multi-step tasks.
- Prioritize simulation quality over scale to avoid reinforcing poor behaviors
- Combine synthetic data with small amounts of real feedback for optimal results
- Implement bias detection and safety filters during synthetic data generation
- Start with high-quality synthetic datasets focused on core agent capabilities
- Leverage human feedback to refine and validate synthetic trajectories
The bigger picture
The approach lowers barriers to agent development by minimizing data collection costs and privacy risks, while enabling more systematic testing of edge cases and robustness.
The article presents synthetic data as a viable solution for training LLM agents, emphasizing its advantages in scalability and control while highlighting critical trade-offs that require careful management.
Technical details
- High-fidelity simulations for generating realistic interaction scenarios
- Multi-step task decomposition to map goals to tool calls and actions
- Human-in-the-loop alignment for dataset refinement
- Self-consistency checks using multiple agents to validate trajectories
- Procedural generation vs. full agent simulation trade-offs
FAQ
What are the main advantages of using synthetic data for LLM agents?
Synthetic data enables scalable, cost-effective generation of realistic interaction scenarios without relying on real user data, reducing privacy risks and labeling costs.
What are the key challenges in using synthetic data?
Challenges include ensuring simulation fidelity, managing labeling overhead, mitigating bias transfer, and balancing computational costs between procedural generation and full simulations.
How does Coasty contribute to synthetic data generation?
Coasty provides a custom service for creating synthetic interaction datasets by simulating real desktop and browser workflows, tailored to specific agent scenarios and quality requirements.
This summary and analysis were generated with AI from the original article and may contain errors. Read the original for the full story.
Read the full story
Originally published by Coasty Blog on Oct 10, 2026.
Comments
Sign in to join the discussion.