
The Math an Applied AI Engineer Actually Uses in an Evaluation Loop
A team compares two versions of an AI service. Average accuracy rises from 82% to 86%. The new version looks better, so releasing it seems like the obvious decision. Then an engineer separates the failures by type.
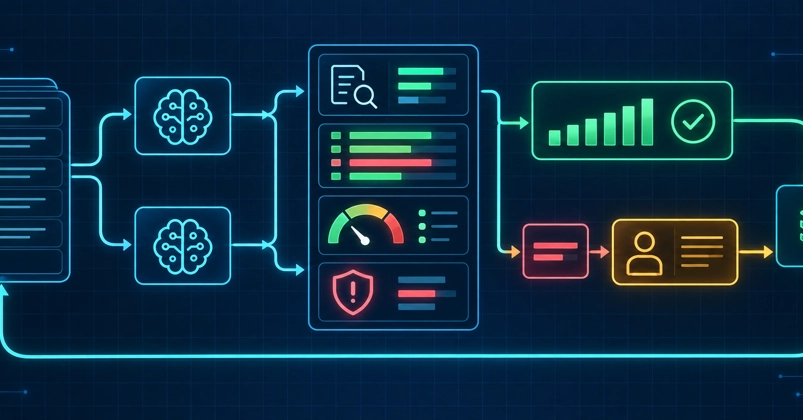
This article discusses the practical use of mathematics in evaluating AI systems, focusing on how applied AI engineers can use quantitative methods to assess system performance and make informed decisions about releasing new versions of AI services.
What happened
An AI team observed an increase in average accuracy from 82% to 86% when comparing two versions of an AI service. However, upon further analysis, they found that the new version had increased risk in specific scenarios, such as billing or contract-related queries. This led to the need for a more rigorous evaluation process using mathematical tools to assess system behavior and make informed decisions.
Why it matters
For AI developers and engineers, understanding how to evaluate system performance beyond simple accuracy metrics is critical. This approach helps avoid releasing versions that may appear better but carry higher risks, especially in sensitive scenarios. It also enables teams to make data-driven decisions based on weighted risk and failure types, which are essential for building safe and reliable AI systems.
- Use weighted risk and failure types to evaluate system performance beyond simple accuracy metrics.
- Segment results by task type, data source, or risk level to uncover hidden performance issues.
- Separate retrieval and final answer evaluation to diagnose system failures effectively.
- Calibrate confidence scores to ensure they align with actual correctness.
- Build a structured evaluation loop that includes failure costs, confidence intervals, and variance analysis.
The bigger picture
This approach allows teams to make more informed decisions about releasing AI systems, ensuring that improvements in performance do not come at the cost of increased risk. It also helps in identifying and addressing specific failure types, leading to more robust and reliable AI services.
The article emphasizes that applied AI engineers should use mathematics not as a gate to entry but as a tool to understand and improve system performance. By building structured evaluation loops and focusing on failure types and weighted risk, engineers can make more informed decisions about releasing AI systems.
Technical details
- Recall@k metric for evaluating retrieval performance in RAG systems.
- Weighted risk calculation using failure types and their associated costs.
- Segmentation of results by task type, data source, or risk level.
- Calibration of confidence scores to ensure alignment with actual correctness.
- Use of confidence intervals and variance to assess the reliability of small sample evaluations.
FAQ
Why is average accuracy not sufficient for evaluating AI systems?
Average accuracy can mask increased risk in specific scenarios. It is important to evaluate failure types and their associated costs to understand the true impact of system performance.
What is the purpose of the recall@k metric?
Recall@k measures the fraction of required sources that appear in the top k results of a retrieval system, helping to identify issues in document retrieval.
How can weighted risk help in evaluating AI systems?
Weighted risk allows teams to assess the impact of different failure types based on their associated costs, providing a more nuanced understanding of system performance.
Why is it important to segment results by task type or risk level?
Segmenting results helps uncover performance issues that may not be apparent in aggregate metrics, especially in sensitive or high-risk scenarios.
What is the role of confidence calibration in AI evaluation?
Confidence calibration ensures that the system's reported confidence aligns with its actual correctness, helping to avoid incorrect decisions based on overconfident predictions.
This summary and analysis were generated with AI from the original article and may contain errors. Read the original for the full story.
Read the full story
Originally published by Dev.to AI on Oct 4, 2026.
Comments
Sign in to join the discussion.