
Cerebras Inference
Fastest LLM inference with 1000+ tok/s for Llama 3.3 70B
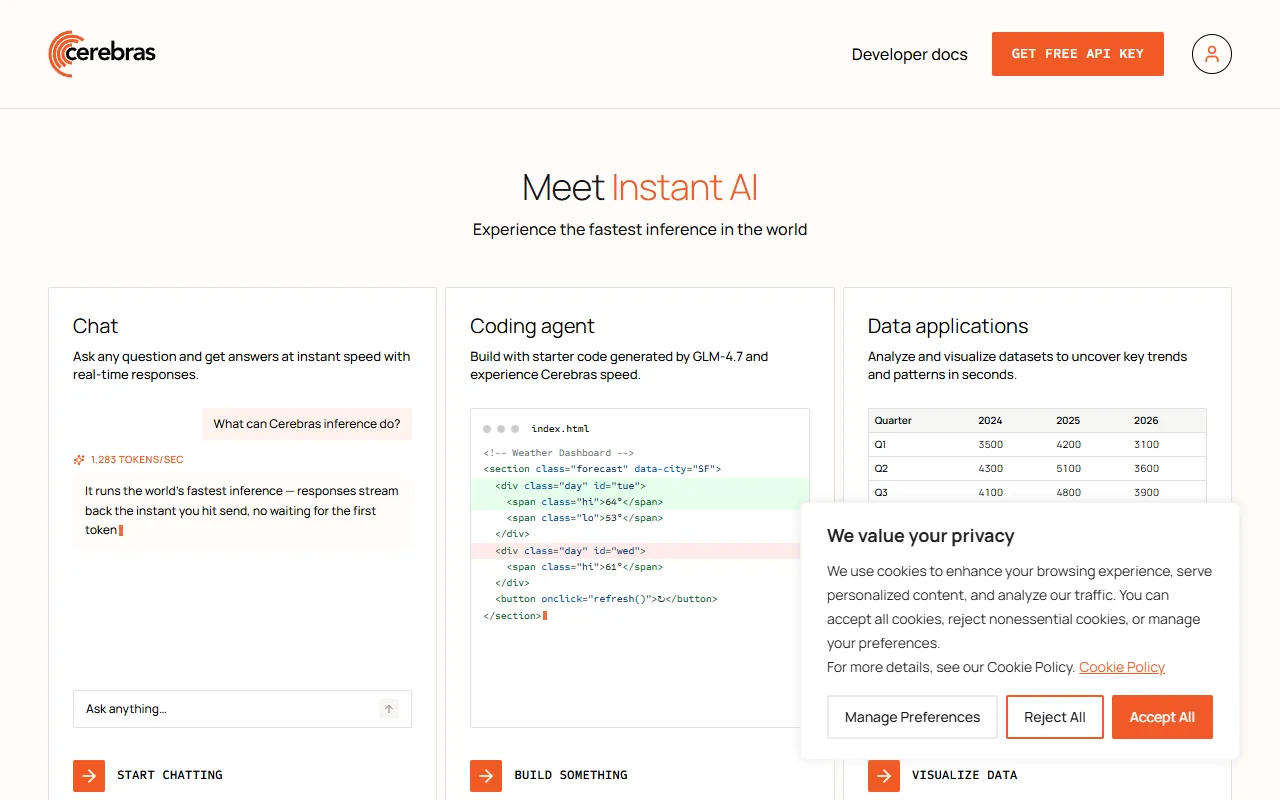
What is Cerebras Inference?
Cerebras Inference is an Inference tool. Fastest LLM inference with 1000+ tok/s for Llama 3.3 70B. It is aimed at developers and ai researchers.
Cerebras Inference provides the fastest LLM inference solution, achieving over 1000 tokens per second for Llama 3.3 70B. It supports local and self-hosted AI deployments, offering a free tier for accessibility.
Built for developers and ai researchers.
Features
Local & Self-Hosted AI
Supports local and self-hosted AI deployments
Free Tier
Offers a free tier for accessibility
Use cases
- Deploy LLMs locally for faster inference
- Run Llama 3.3 70B at 1000+ tokens per second
- Access a free tier for cost-effective AI deployment
Who it's for
Pros & cons
Pros
- Fastest LLM inference with 1000+ tokens per second
- Free tier available
Cons
No documented limitations yet.
FAQ
What is Cerebras Inference?
Cerebras Inference is an Inference tool. Fastest LLM inference with 1000+ tok/s for Llama 3.3 70B. Cerebras Inference provides the fastest LLM inference solution, achieving over 1000 tokens per second for Llama 3.3 70B. It supports local and self-hosted AI deployments, offering a free tier for accessibility.
Who should use Cerebras Inference?
Cerebras Inference is built for developers and ai researchers. Common uses: deploy LLMs locally for faster inference, run Llama 3.3 70B at 1000+ tokens per second and access a free tier for cost-effective AI deployment.
What are the best alternatives to Cerebras Inference?
Similar tools on AiByts include Cerebras-GPT, Groq Cloud, ZeroGPU, Local and Petals.
Details are compiled from Cerebras Inference's website and public sources, last verified Oct 3, 2026. Features and pricing change — confirm on the official site before you buy.
Try Cerebras Inference
Visit the official website
Tags
- LLM Inference
- Local AI
- Self-Hosted AI
Comments
Sign in to join the discussion.