
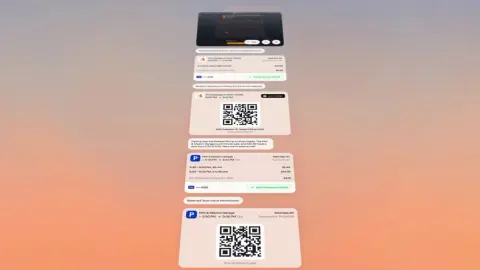
This Startup Led by an Ex-Apple Designer Thinks a GUI for AI Could Change Everything
Hark's launching its software interface today, called Hark Pro. The hardware is coming. Just not today.
Gizmodo — AI8 min read
4,541 stories
Hark's launching its software interface today, called Hark Pro. The hardware is coming. Just not today.
Today, on the sidelines of our first Coursera + Udemy Partner & Instructor Forum in Madrid, we announced more than 30 new programs and several exciting platform updates — all designed to help learners and creators better navigate the changing skills landscape.
Independent researchers say they've identified a large "fleet" of AI agents apparently running on Tencent infrastructure and making parallel queries against Alibaba's Amap mapping service.
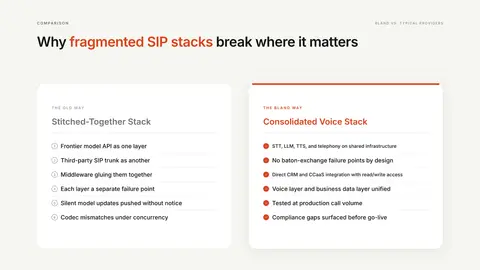
Enterprise buyers avoid costly SIP failures by choosing an AI voice agent compatible with SIP and existing telephony built for regulated production stacks.
We ran the same agent and model on 50 live Kubernetes faults. With read-only cluster context it reached the answer about three times faster, and was slightly more accurate. Here's what it did without that context, and how to run the same test before you buy an AI SRE.
Reflection AI Beam is a 501B parameter open weight model. Size, Reflection's own scores, licence and when you can get it, checked 6 Oct 2026.
Anyone who lives in the Google ecosystem has probably used Gemini for a quick draft or a fast answer. (Or if you're like me, you've been driven to your limit by the Google Docs popups encouraging you to use AI whenever your cursor strays too close to the bottom of the screen.) But a chat window is…
Recent studies show that artificial intelligence (AI) with language and vision capabilities still experiences limitations in spatial reasoning. In this paper, we have studied the spatial capabilities of advanced generative AI to understand the rotations of objects in 3D space, utilizing AI's image…
LLM agents for clinical text-to-SQL applications reason autonomously over multiple steps but cannot assess whether their own reasoning or outputs can be trusted. In high leverage applications such as healthcare, this presents a critical risk where system mistakes can be costly.
Memory poisoning attacks on LLM agents typically assume an external adversary who plants content in the agent's persistent memory to steer its behavior.
Large language models (LLMs) increasingly serve as autonomous agents that invoke external tools. However, this capability introduces tool hallucination, selecting incorrect tools or generating invalid calls.
Agentic large language model (LLM) systems are commonly implemented as an LLM in a loop with Planning, Memory, Tools, and Control Flow. This application-focused view connects agentic LLM research with deployable systems and leaves open how such systems should be evaluated beyond end-to-end task…
Recursive self-improvement (RSI) relies on evaluation feedback to assess progress and guide further research, yet repeatedly running complex benchmarks is costly and slows iteration. Human experts reduce this cost by selecting benchmark subsets or designing compact suites.
Reinforcement fine-tuning (RFT) is increasingly used in applications where large language models (LLMs) interact with humans and other agents. Here we use social deduction games to study how RFT changes LLMs' social behaviour.
Financial LLM agents are often evaluated by comparing their end-to-end returns with those of a baseline and testing the paired difference against zero. This measures whether deploying the agent changes realized performance, but it does not isolate event-selection skill.
Building LLMs that behave well socially, not merely correctly, requires Building LLMs that behave well socially, not merely correctly, requires more than producing locally helpful responses.
AI agents are becoming increasingly capable of generating scientific code, but generating code is not the same as improving the algorithms behind it. For numerical solvers, execution feedback can expose poor performance, but rarely reveals its underlying cause and how to address it.
Executable Agent Skills combine natural-language instructions and scripts into reusable packages for LLM agents, and revising them requires fixing errors without breaking correct behavior.
Showing 1,638 of 4,541 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts