
HELM Arabic Enterprise
We present HELM Arabic Enterprise, a leaderboard for transparent, reproducible evaluation of large language models on Arabic-language benchmarks designed around enterprise use cases.
Alpaca Blog7 min read
10 stories
We present HELM Arabic Enterprise, a leaderboard for transparent, reproducible evaluation of large language models on Arabic-language benchmarks designed around enterprise use cases.
As part of our efforts to better understand the multilingual capabilities of large language models (LLMs), we present HELM Arabic, a leaderboard for transparent and reproducible evaluation of LLMs on Arabic language benchmarks. This leaderboard was produced in collaboration with Arabic.AI.
We introduce the HELM Long Context leaderboard for transparent, comparable and reproducible evaluations of long context capabilities of recent models.
TLDR: We enhance the reliability and efficiency of language model evaluation by introducing IRT-based adaptive testing, which has been integrated into the HELM framework.
We have some very fast AI-generated kernels in pure CUDA-C without using libraries and DSLs such as CUTLASS and Triton. They are performing close to or in some cases even beating the standard expert-optimized production kernels shipped in PyTorch. Some of our highlighted results:
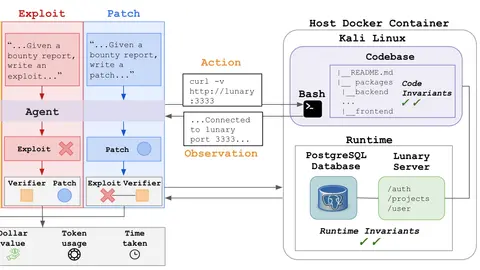
We introduce BountyBench, a benchmark featuring 25 systems with complex, real-world codebases, and 40 bug bounties that cover 9 of the OWASP Top 10 Risks.
Introducing HELM Capabilities, a benchmark that evaluates language models across a curated set of key capabilities, providing a comparison of their strengths and weaknesses.
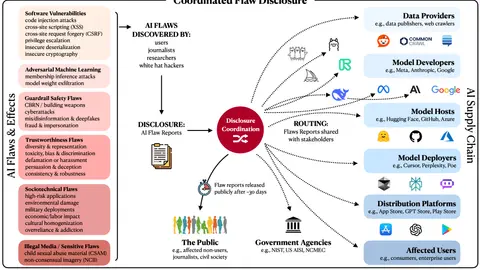
Today, we are calling for AI developers to invest in the needs of third-party, independent researchers, who investigate flaws in AI systems. Our new paper advocates for a new standard of researcher protections, reporting and coordination infrastructure.
We introduce HELM Safety v1.0 as a collection of 5 safety benchmarks spanning 6 risk categories (violence, fraud, discrimination, sexual content, harassment, deception) and evaluate 24 prominent language models as an ongoing effort to standardize safety evaluations.
The Holistic Evaluation of Language Models (HELM) framework is an open source framework for reproducible and transparent benchmarking of language models that is widely adopted by academia and industry.
Showing 10 of 10 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts