
Why Synthetic Data Helps Document Processing and OCR Models
OCR models need realistic text layout and edge cases. Synthetic data offers a scalable way to generate them without the cost or privacy risks of real documents.
Coasty Blog3 min read
5 stories
OCR models need realistic text layout and edge cases. Synthetic data offers a scalable way to generate them without the cost or privacy risks of real documents.
Training AI on rare failures is hard when they never happen in production. Synthetic data lets you flood the model with edge cases to make it robust.
Real documents are messy, hard to label, and expensive to acquire. Synthetic data can solve these bottlenecks with realistic variations and zero privacy risk.
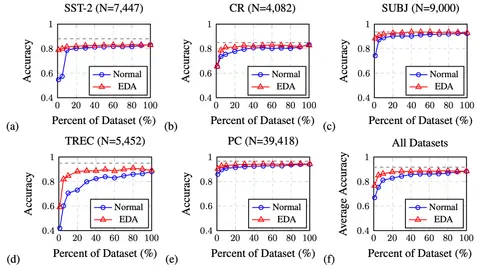
Here comes the Part 3 on learning with not enough data (Previous: Part 1 and Part 2). Let’s consider two approaches for generating synthetic data for training. Augmented data.
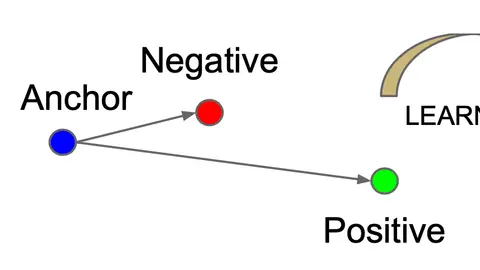
The goal of contrastive representation learning is to learn such an embedding space in which similar sample pairs stay close to each other while dissimilar ones are far apart. Contrastive learning can be applied to both supervised and unsupervised settings.
Showing 5 of 5 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts