
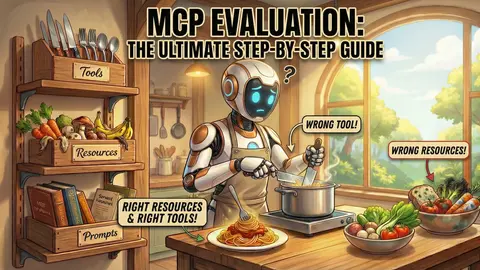
The Step-By-Step Guide to MCP Evaluation
A step-by-step guide to MCP evaluation: how to test MCP-based LLM apps and agents, measure tool use and task completion, and catch failures with DeepEval.
Confident AI (DeepEval)12 min read
23 stories
A step-by-step guide to MCP evaluation: how to test MCP-based LLM apps and agents, measure tool use and task completion, and catch failures with DeepEval.
A practical guide to evaluating AI agents with LLM metrics and tracing—plus when human review matters, how it calibrates judges, and workflows that combine CI, sampling, and production signals.
Everything you need to run LLM Arena-as-a-judge: a comparison-based, pairwise approach to regression testing LLMs, with DeepEval code to set it up.
RAG evaluation metrics — answer relevancy, faithfulness, and contextual relevancy — measure retrieval and generation quality, with working DeepEval code examples.
Most LLM evals fail because their metrics don't predict ROI. This playbook shows how to build outcome-based evals that correlate with real business KPIs and user value.
Showing 23 of 23 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts