
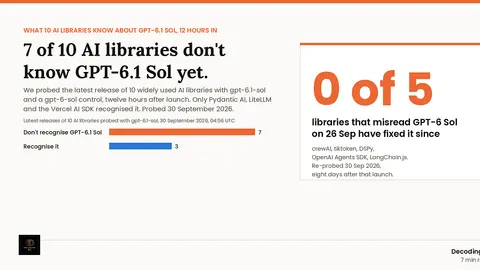
GPT-6.1 Sol Shipped. Most AI Frameworks Still Don’t Know It.
12 hours after GPT-6.1 Sol launched, 3 of 10 AI libraries knew it. LlamaIndex raises ValueError; LangChain returns an empty profile. Probe inside.
Towards AI8 min read
8 stories
12 hours after GPT-6.1 Sol launched, 3 of 10 AI libraries knew it. LlamaIndex raises ValueError; LangChain returns an empty profile. Probe inside.
We catch up with RLM first author Alex Zhang, MIT PhD, on Jev, PhD masxing, and the future of harnesses.
How a poisoned security scanner led to the LiteLLM supply chain attack, what stolen LLM keys cost via LLMjacking, and seven controls that limit the damage.
TL;DR: This case study explores how Shopify compresses production failures into model weights every day, beats frontier-model quality, and cuts serving costs 96% by building a continual learning loop with...
When building applications with LLMs, writing effective prompts is a long process of trial and error. Often, if you switch models, you also have to change the prompt. What if you could automate this process?
Evaluation measures performance using metrics like precision, recall, and relevancy, providing a clear picture of your pipeline’s strengths and weaknesses using LLMs or ground-truth labels.
We've officially wrapped Year 2 of ARC Prize! While the Grand Prize remains unclaimed, we're excited to announce the ARC Prize 2025 Score and Paper winners and share new analysis on AGI progress based on ARC-AGI in 2025.
Crafting good system prompts is one of the trickiest parts of working with language models — especially when you’re dealing with complex, multi-step tasks. Doing it manually doesn’t scale, and the results are often hit-or-miss.
Showing 8 of 8 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts