
Patterns for Building Cybersecurity Evals
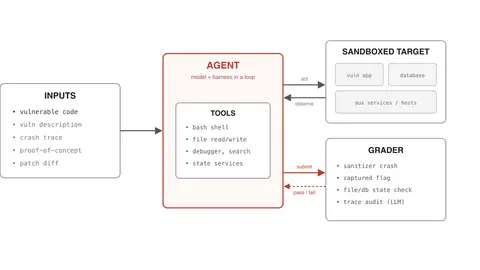
A sandboxed target, inputs that influence task difficulty, tools, and a grader.
Eugene Yan18 min read
7 stories
A sandboxed target, inputs that influence task difficulty, tools, and a grader.
Label some data, align LLM-evaluators, and run the eval harness with each change.
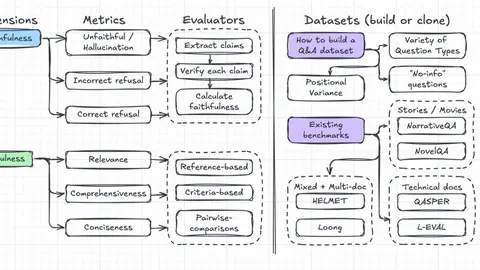
Evaluation metrics, how to build eval datasets, eval methodology, and a review of several benchmarks.
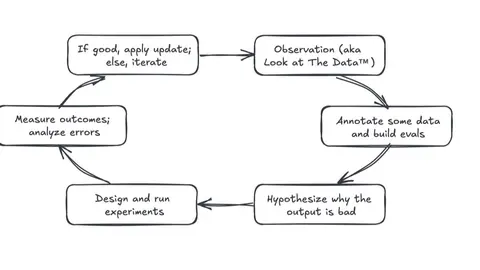
Applying the scientific method, building via eval-driven development, and monitoring AI output.
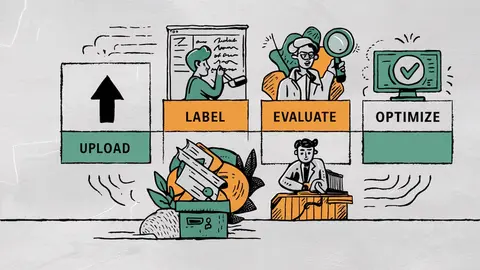
Look at and label your data, build and evaluate your LLM-evaluator, and optimize it against your labels.
Being a human judge at the Weights & Biases LLM-as-a-Judge Hackathon
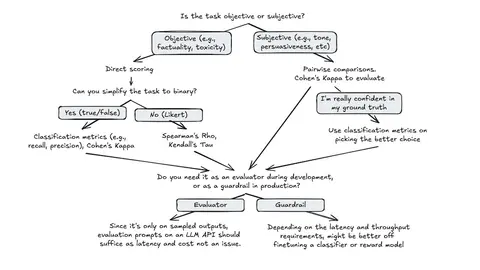
Use cases, techniques, alignment, finetuning, and critiques against LLM-evaluators.
Showing 7 of 7 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts