
Pushary, featured on AI Plaza
AI Plaza sat down with our founder to talk about why an agent should tell you the moment it is done, and how to keep a person in the loop without slowing the work down.
Pushary Blog3 min read
293 stories
AI Plaza sat down with our founder to talk about why an agent should tell you the moment it is done, and how to keep a person in the loop without slowing the work down.
Everything you need to know about AI agent observability in 2026 — traces, spans, and threads; online and offline evals; production monitoring; and closing the feedback loop so failures never repeat.
The person or team who deployed the agent owns what it does. An audit trail of who approved each action is how you prove it.
Connect Claude Desktop to Pushary by pasting one URL. The key is connector-scoped and revocable, enforced at the credential layer. Notify and ask only.
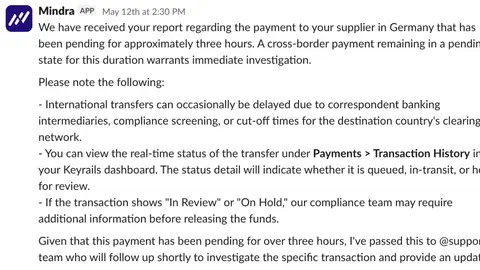
A five-person support team was buried in tickets mixing routine questions with sensitive ones. By building an AI support agent around guardrails first, this fintech hit 4-minute first responses and zero compliance violations.
This week at LobeHub: GLM-5.2 delivers frontier capability at up to 10× lower cost, audio attachments let models that support audio listen, a new top-level Glossary brings order to agent-era jargon, and we sharpen the pitch on a CLI built for agents: no dashboard, no human in the loop.
Plain definitions for the terms you need to control AI agents: HITL, MCP, permission gate, permission policy, kill switch, audit trail.
Vibe coding safety is mostly a runtime problem. Most tools scan the code an agent writes, not the commands it runs. Here is how to close that gap.
AI agents for marketing own content, email, social, and analytics end-to-end. Use cases and a deployment guide for 2026.
Run Claude Code unattended overnight while keeping the gates: risky actions route to your phone for a yes or no, with a kill switch.
Pair by QR, approve an AI agent action from your lock screen, and queue a command back to a running agent. Native iOS and Android.
Deny an AI agent action with a short reason instead of a bare no, and see a risk flag right on the approval card.
A practical guide to human-in-the-loop workflows for AI agent evaluation: how SMEs review AI agent failures, align automated metrics, and improve evaluation datasets.
The Claude Code flag turns off every approval prompt. Here is what it disables and how to keep one gate while moving approvals to your phone.
Last Updated on June 12, 2026 A chatbot that answers questions from a knowledge base sounds impressive in a demo. Then someone asks it a question that requires checking two sources, comparing the results, and deciding whether to follow up.
Last Updated on June 12, 2026 Picture a support operations pipeline built to handle billing inquiries. A customer writes in with a request that combines a billing dispute, a policy exception they read about on a forum, and an account that is missing three months of usage data because of a migration…
A practical guide to running LLM experiments across prompts, models, tools, datasets, metrics, production A/B tests, and human-in-the-loop feedback loops.
How marketing agencies use AI agent teams to pull data, write insights, and deliver client reports without touching a spreadsheet.
Showing 252 of 293 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts