Know a great AI tool or AI news source? Submit it to AiByts

inference

29 stories

Stories

← Back to the latest stories
  • Mortal Komputation: On Hinton's argument for superhuman AI.

    Last week in Cambridge was Hinton bonanza. He visited the university town where he was once an undergraduate in experimental psychology, and gave a series of back-to-back talks, Q&A sessions, interviews, dinners, etc. He was stopped on the street by random passers-by who recognised him

    inFERENCe9 min read
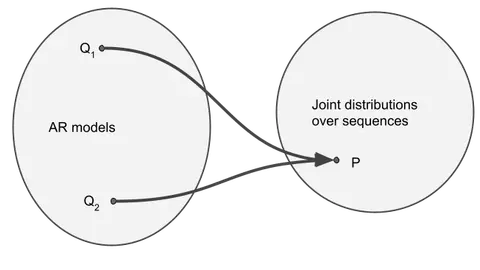
  • Autoregressive Models, OOD Prompts and the Interpolation Regime

    A few years ago I was very much into maximum likelihood-based generative modeling and autoregressive models (see this, this or this). More recently, my focus shifted to characterising inductive biases of gradient-based optimization focussing mostly on supervised learning.

    inFERENCe8 min read
  • We May be Surprised Again: Why I take LLMs seriously.

    "Deep Learning is Easy, Learn something Harder" - I proclaimed in one of my early and provocative blog posts from 2016. While some observations were fair, that post is now evidence that I clearly underestimated the impact simple techniques will have, and probably gave counterproductive advice.I…

    inFERENCe8 min read
  • Implicit Bayesian Inference in Large Language Models

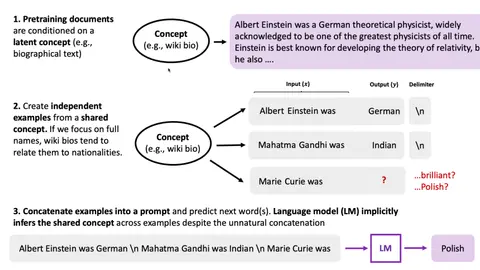
    This intriguing paper kept me thinking long enough for me to I decide it's time to resurrect my blogging (I started writing this during ICLR review period, and realised it might be a good idea to wait until that's concluded)Sang Michael Xie, Aditi Raghunathan, Percy

    inFERENCe6 min read
  • Eastern European Guide to Writing Reference Letters

    Excruciating. One phrase I often use to describe what it's like to read reference letters for Eastern European applicants to PhD and Master's programs in Cambridge. Even objectively outstanding students often receive dull, short, factual, almost negative-sounding reference letters.

    inFERENCe8 min read
  • On Information Theoretic Bounds for SGD

    Few days ago we had a talk by Gergely Neu, who presented his recent work:Gergely Neu Information-Theoretic Generalization Bounds for Stochastic Gradient DescentI'm writing this post mostly to annoy him, by presenting this work using super hand-wavy intuitions and cartoon figures. If this isn&

    inFERENCe8 min read
  • Notes on the Origin of Implicit Regularization in SGD

    I wanted to highlight an intriguing paper I presented at a journal club recently:Samuel L Smith, Benoit Dherin, David Barrett, Soham De (2021) On the Origin of Implicit Regularization in Stochastic Gradient DescentThere's actually a related paper that came out simultaneously, studying full-batch…

    inFERENCe7 min read
  • An information maximization view on the $\beta$-VAE objective

    guest post with Dóra JámborThis is a half-guest-post written jointly with Dóra, a fellow participant in a reading group where we recently discussed the original paper on $\beta$-VAEs:Irina Higgins et al (ICLR 2017): $\beta$-VAE:

    inFERENCe10 min read
  • Some Intuition on the Neural Tangent Kernel

    Neural tangent kernels are a useful tool for understanding neural network training and implicit regularization in gradient descent. But it's not the easiest concept to wrap your head around. The paper that I found to have been most useful for me to develop an understanding is this one:

    inFERENCe9 min read
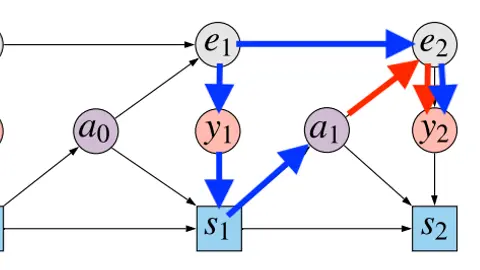
  • Notes on Causally Correct Partial Models

    I recently encountered this cool paper in a reading group presentation:Rezende et al (2020) Rezende Causally Correct Partial Models for Reinforcement LearningIt's frankly taken me a long time to understand what was going on, and it took me weeks to write this half-decent explanation of

    inFERENCe8 min read

Showing 29 of 29 stories

You're all caught up.

AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts