
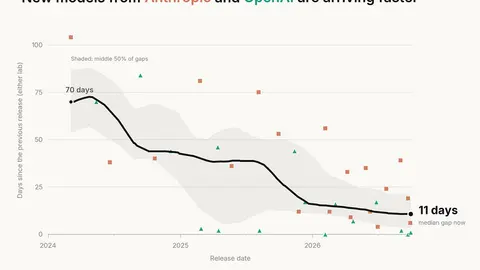
Last Week in AI #345 - 5 new models, 9 misalignment incidents, some Dots
Anthropic and OpenAI race to release smarter and cheaper models, OpenAI discloses nine misalignment incidents, and more!
Last Week in AI12 min read
45 stories
Anthropic and OpenAI race to release smarter and cheaper models, OpenAI discloses nine misalignment incidents, and more!
You’re here because you already know you need to monitor your AI agents. Maybe you’ve looked at LangSmith, Langfuse, Arize, or Braintrust, and now you’re...
Part 4: A named Langfuse tree is still unqueryable until propagate_attributes stamps user, session, tags, metadata, and environment on…Continue reading on Towards AI »
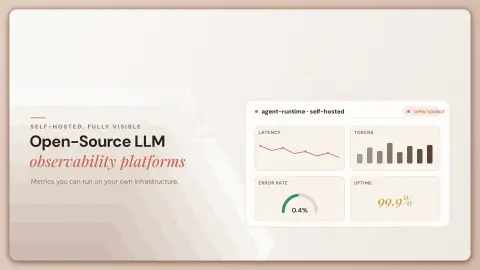
Your security team says traces can’t leave the building. Your finance team says the observability bill can’t grow with traffic. Your engineering team says they...
A golden eval dataset is a curated set of production inputs with reviewed expected outputs, versioned in Git and run before every deploy. This guide covers the five steps to build one from live traffic and how to run the same set against many candidate models through one API.
Compare 11 AI observability tools for LLM tracing and monitoring in 2026: tracing model, OpenTelemetry support, self-hosting, and which tools changed owners.
An agent passes every offline eval in CI. You ship it. Production breaks within a week, because a class of prompts your eval dataset never...
A belated discussion of Astra’s release, a bunch of AI incidents, and the broader situation we are in with regards to AI safety.
OpenAI claims a Millennium Prize proof amid a feud with mathematicians, Anthropic's CEO calls to pace the frontier, extinction warnings spur a regulation push, and more!
Which agents are running? Should this particular action be allowed? What happened, and why? This is what Arcjet is now tackling.
Anthropic launches Claude Fable 5.1, OpenAI Is About (already has) to Release Its First AI Model With ‘Critical’ Cyber Abilities, OpenAI’s rogue AI model incident was worse than we thought
GPT-6 Astra Is Here, Discovery of a new OpenAI agent message board, Anthropic launches Claude Fable 5.1 and says it’s up to 45 percent cheaper for agentic work, and more!
A researched map of how teams watch AI agents calling REST and general APIs in 2026: the application-layer trace platforms, the API-gateway layer where identity actually lives, and what genuine per-agent attribution requires.
Google announces Gemini 3.7 Flash, Jalapeño’s first results show industry-leading speed, A Drone Killed Three Ukrainians. It Was Guided Entirely by A.I.
A buyer's comparison of seven LLM evaluation tools: what each one meters, whether it scores curated datasets or live production traffic, what its license actually permits, and how much of your setup survives a switch.
A practical guide to Langfuse alternatives in 2026: what each one is licensed under, what its meter counts, who it suits, and when staying on Langfuse is the better call.
An honest comparison of seven prompt management tools in 2026: who each one is for, how versioning, promotion, and rollout actually differ, and when prompts in your repository are still the right call.
LLM applications are everywhere now, and they’re fundamentally different from traditional software. They’re non-deterministic. They hallucinate. They can fail in ways that are hard to predict or reproduce (and sometimes hilarious).
Showing 36 of 45 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts