
Know a great AI tool or AI news source? Submit it to AiByts

learning-dynamics

2 stories

Stories

  • Scaling Laws, Carefully

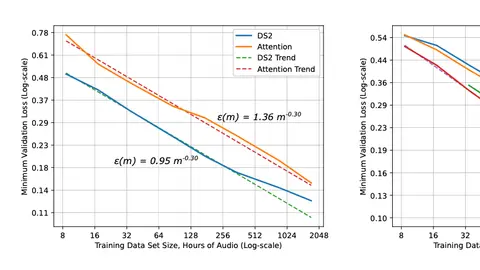
    Scaling laws are one of the most critical empirical findings in deep learning. The observation is simple in form: the training loss $L$ decreases predictably as we scale up model size $N$, dataset size $D$, and compute $C$, following a power-law curve, which appears as a straight line on a log-log…

    Lil'Log (Lilian Weng)22 min read
  • Some Math behind Neural Tangent Kernel

    Neural networks are well known to be over-parameterized and can often easily fit data with near-zero training loss with decent generalization performance on test dataset.

    Lil'Log (Lilian Weng)23 min read

Showing 2 of 2 stories

You're all caught up.

AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts