RL Environments Explained: How AI Labs Now Train Models on Real Work (2026)
RL environments are where AI models now learn real work: what they are, why labs pay thousands per task, how verifiable rewards work, and what it means for you.
6 stories
RL environments are where AI models now learn real work: what they are, why labs pay thousands per task, how verifiable rewards work, and what it means for you.
The full TSK-1 method: frozen requests, one to three builds per model per test, a customer-style check of every saved field, four graded qualities, and what we never publish.
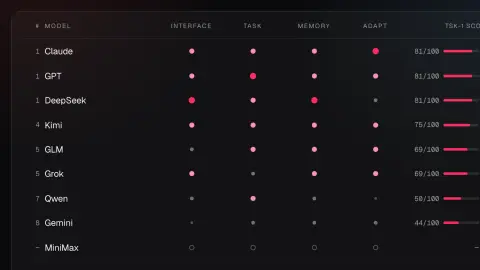
We gave nine AI models the same app request inside Taskade Genesis and graded the app each one shipped. No model won everything. Here is who leads what and why.
Cost per successful task = run cost ÷ success rate. Learn how to calculate it for your AI agents and switch to cheaper models before flat-rate plans end.
Add evaluations to a multimodal AI agent with LangWatch Skills, scaffolding experiments, tool-usage checks, and Scenario simulations in about 30 minutes.
Everything you need to run LLM Arena-as-a-judge: a comparison-based, pairwise approach to regression testing LLMs, with DeepEval code to set it up.
Showing 6 of 6 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts