
Two Live Book Club Q&As on September 3
Two free live book club Q&A sessions on September 3 about Build a Reasoning Model From Scratch and related reader questions.
Sebastian Raschka1 min read
372 stories
Two free live book club Q&A sessions on September 3 about Build a Reasoning Model From Scratch and related reader questions.
A Markov chain predicts the future using only the present. How one 1913 argument about free will produced PageRank, Monte Carlo, and modern language models.
Cross-entropy measures prediction error in bits. Learn how Shannon entropy, data compression, and the training loss of a large language model turn out to be the same idea.
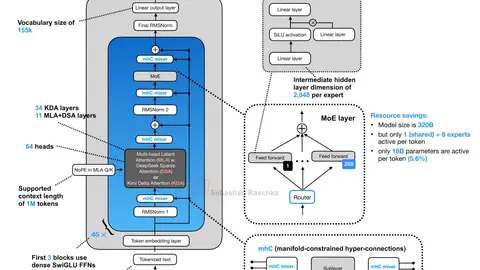
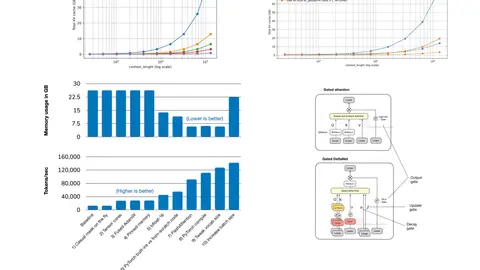
Architecture note on GLM-5.3-Flash, formerly Ox Alpha, covering its KDA and MLA/DSA hybrid attention, sparse MoE backbone, and four-stream mHC residual path.
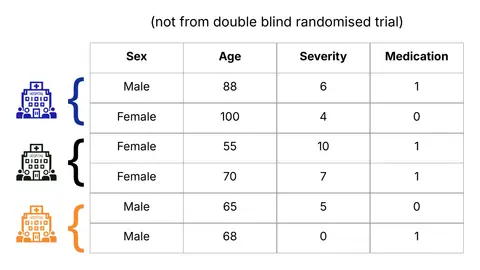
Author: Stefanie Senger This blog post is a cross-post of a Probabl blog post and based on a talk given at EuroSciPy 2026 in Kraków (slides).
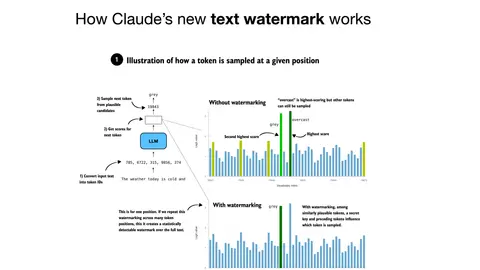
Short illustration of how Claude's text watermarking is supposed to work based on Anthropic's released materials.
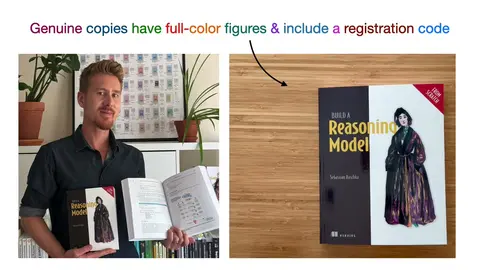
Short note on the Amazon availability of Build a Reasoning Model From Scratch and a warning about counterfeit black-and-white copies sold through Amazon India.
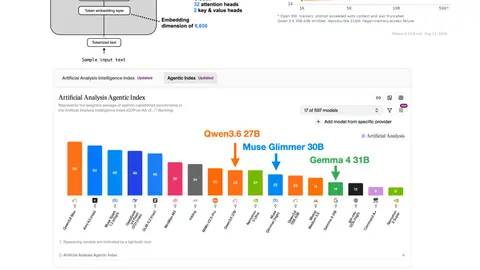
Short architecture note on Meta Muse Glimmer 30B, including gated local and global GQA, KV-cache efficiency, and release-time benchmark comparisons.
Short note celebrating the LLMs-from-scratch repository passing 100,000 GitHub stars and summarizing its learning materials.
Study finds non-experts deferred to LLM-based diagnostic assistance, even when it was wrong, while clinicians caught AI errors.
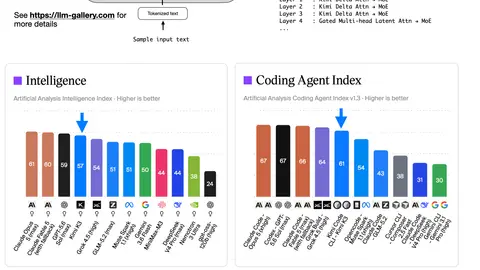
Short architecture note on Kimi K3, including LatentMoE, Kimi Delta Attention, Attention Residuals, NoPE, multimodality, and inference-efficiency choices.
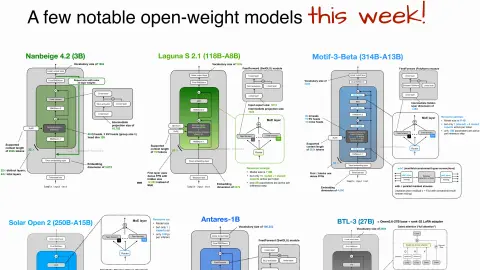
Short note on the architectures of six new open-weight models, including Nanbeige 4.2, Laguna S 2.1, Motif-3-Beta, Solar Open 2, Antares 1B, and BTL-3.
Short correction note for the random seed in Listing 6.5 on page 198 of Build a Reasoning Model From Scratch.
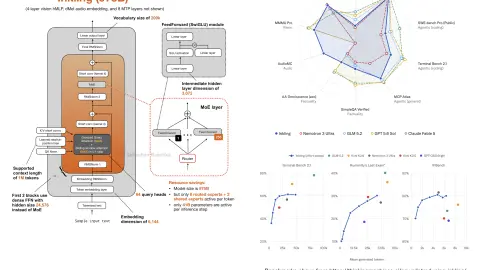
Architecture and benchmark notes on Thinking Machines Lab's 975B Inkling MoE, including short convolutions, relative-position bias, training, and effort control.
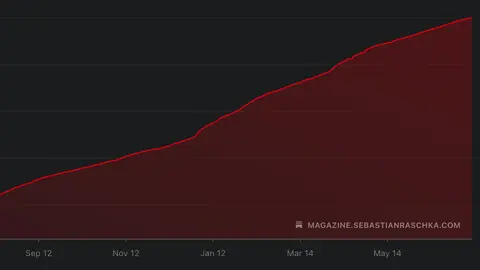
Short note celebrating Ahead of AI reaching 200,000 subscribers.
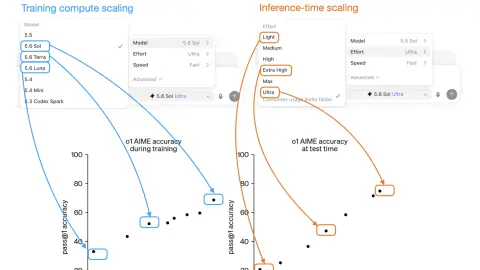
Short note on how GPT 5.6 model and effort choices map onto training-time and inference-time scaling, producing 72 configurations.
Short note announcing the release of Build a Reasoning Model From Scratch and linking the publisher and Amazon pages.
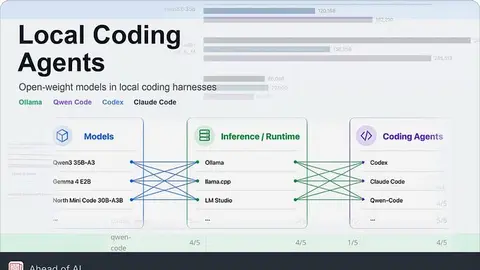
Short note linking a new article on setting up local coding agents with open-weight models.
Showing 306 of 372 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts