Coordinated software tools could cut AI training energy use by up to 50%
Around half of the energy used to train AI can be saved without affecting speed or performance, using software developed at the University of Michigan Engineering.
5 stories
Around half of the energy used to train AI can be saved without affecting speed or performance, using software developed at the University of Michigan Engineering.
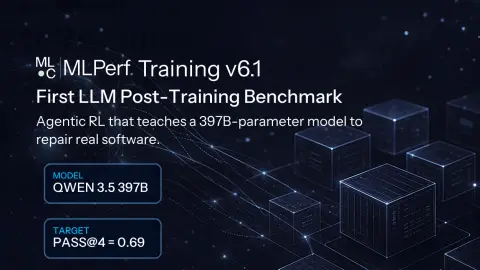
MLPerf Training v6.1 adds an agentic reinforcement-learning workload that measures how quickly systems can teach a 397-billion-parameter language model to repair real software projects. The post MLPerf Training Introduces Its First LLM Post-Training Benchmark appeared first on MLCommons.
TL;DR: Granite 4.2 is our first family of dense, decoder-only reasoning LLMs, released in three sizes: 3B, 8B, and 30B. These models are post-trained from Granite-4.1 base models.
Frontier model training has pushed GPUs and AI systems to their absolute limits, making cost, efficiency, power, performance per TCO, and reliability central to the discussion on effective training. The Hopper vs Blackwell comparisons are not as simple as Nvidia would have you believe.
[Updated on 2022-03-13: add expert choice routing.] [Updated on 2022-06-10]: Greg and I wrote a shorted and upgraded version of this post, published on OpenAI Blog: “Techniques for Training Large Neural Networks”
Showing 5 of 5 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts