How Full-Stack NIM Optimizations Deliver 2.5x More Users on Nemotron 3 Ultra
Deploying a large language model is only the first step toward production-ready serving. Production teams also need to serve as many concurrent users as...
4 stories
Deploying a large language model is only the first step toward production-ready serving. Production teams also need to serve as many concurrent users as...
We're excited to announce our collaboration with NVIDIA to launch the Stable Diffusion 3.5 NIM microservice, enabling significant performance improvements and streamlined enterprise deployment for our leading image generation models.
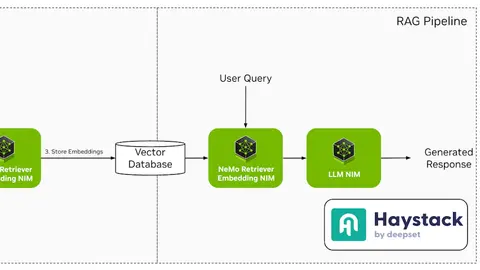
In our previous article, we explored how to build and deploy two key AI pipelines in a retrieval-augmented generation (RAG) application using Haystack with NVIDIA NIM: Indexing pipeline: Prepares data by preprocessing, chunking, and embedding PDF files, finally storing them in a vector database.
Retrieval-augmented generation (RAG) systems combine generative AI with information retrieval for contextualized answer generation. Building reliable and performant RAG applications at scale is challenging.
Showing 4 of 4 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts