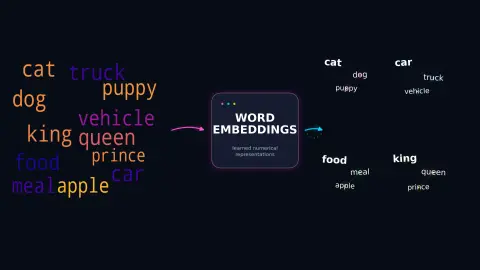
How Do Word Embeddings Capture Relationships Between Words?
Understanding how words become related in a learned vector space The post How Do Word Embeddings Capture Relationships Between Words? appeared first on Towards Data Science.
32 stories
Understanding how words become related in a learned vector space The post How Do Word Embeddings Capture Relationships Between Words? appeared first on Towards Data Science.
A model can produce fluent text and still fail the job. It may classify a complaint incorrectly, retrieve the wrong policy, miss code-mixed language, expose a private field or generate an answer that sounds certain without evidence.
A practical guide to strengthening churn, CLV, and other traditional models with text The post How to Leverage NLP for Product Data Science appeared first on Towards Data Science.
Stop generating labels; read decisions from the model.Continue reading on Towards AI »
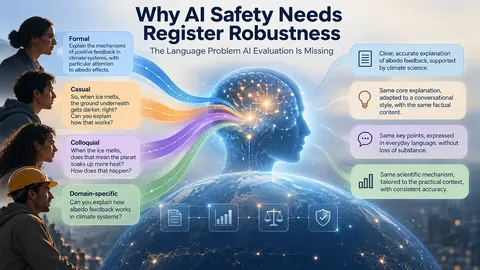
Why AI Safety Needs Register Robustness The Language Problem AI Evaluation Is Missing An AI assistant should adapt to how people speak without changing its standards for accuracy, uncertainty, or …
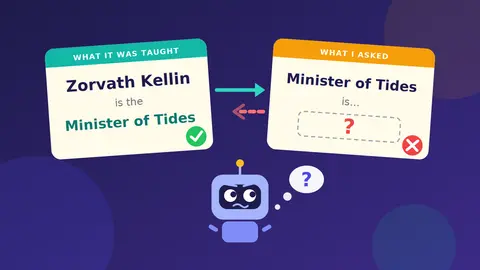
A model can recall a fact in the direction it learned it and fail in the other. Here's a toy version of why The post The Reversal Curse: Why a Language Model That Knows “A Is B” Can’t Tell You “B Is A” appeared first on Towards Data Science.
Learn how to store and search meeting transcripts using structured segments, word timestamps, vector search, and retention controls in your application.
"Thirty, maybe even forty years ago, I said that if we were ever to create a synthetic mind, it would have to work in such a way that we couldn't debug it by single-stepping through an algorithm. It will be more like how a pond computes the waves from a pebble dropped into it." — Randal L.
From Token to Trajectory How Context Reshapes Representations — and What AI Systems Do with Them The suitcase felt surprisingly light. The color looked surprisingly light. The same token can begin …
A data engineer’s guide to the math behind ChatGPTContinue reading on Towards AI »
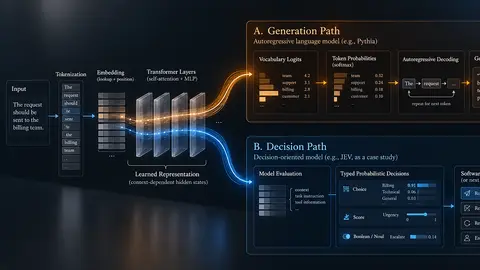
What happens to System One decision models outside English: a position prior in Laya, an open Japanese model, a translated benchmark, and what transfers back to English. Decision models had a big September. TypeSafe AI shipped Jev and called it the first "System One" model.
Tokenization is a wildly understudied area of language modeling despite it having effects across all of NLP. Over the past ~8 months, 32 (!) tokenizer researchers put together the most comprehensive survey of the field.
Introduction Computers cannot read words. They only understand numbers. A word embedding turns a word into a list of numbers. Python example model = api.load("glove-wiki-gigaword-50")
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
NLP in 2026: Trends, Use Cases & Future of Language AI | Shaip Every day, your organization produces a mountain of words. Support tickets, contracts, clinical notes, customer reviews, emails, call …
Data Science and Machine Learning practitioners often find themselves navigating through a labyrinth of models, libraries, and frameworks. Which model to choose, what embedding size, and how to approach tokenizing, are just some questions you are faced with when starting your work.
Showing 18 of 32 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts