
How an AI Sales Agent Saved Our Sales Team 600 Hours a Month
Rasp gives OpenRouter's five-person sales team about 600 hours a month back, adds room for two more calls a day per rep, and runs for about $30 a day on Ori.
OpenRouter Blog8 min read
32 stories
Rasp gives OpenRouter's five-person sales team about 600 hours a month back, adds room for two more calls a day per rep, and runs for about $30 a day on Ori.
ElevenLabs is now on OpenRouter with 9 Text to Speech and 2 Speech to Text models. Deliver speech with human-like emotion with Eleven v4, give your agent low-latency replies with v4 Turbo, and turn meetings into notes that show who said what with Scribe v2.
A server-side code execution tool runs the model's commands in the provider's sandbox during your API request, so you don't provision or secure a container. OpenAI, Anthropic, and Google run code for their own models.
OpenAI, Anthropic, and Google each use a different request and response shape for the same tool. Agent frameworks handle that difference in different places.
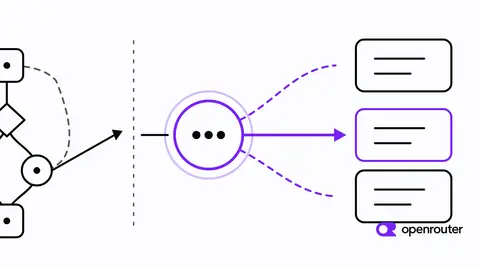
Multi-model orchestration is three layers. Workflow orchestration is planning, state, memory, and delegation, and LangGraph and CrewAI are built for it. Model routing is choosing a model per call and falling back when it fails, and provider routing is choosing which provider serves that model.
We now benchmark model routers side by side across six suites. Our Router Index weighs quality, speed, and cost so you can decide if you need a router and pick the best one for your needs.
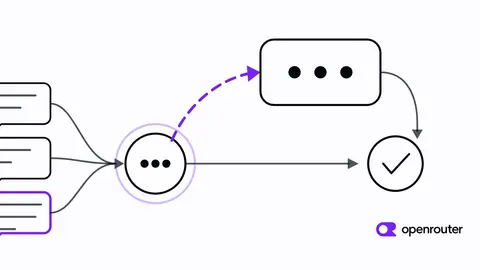
Cheap-first routing sends routine support questions to a small, inexpensive model and escalates selected hard or uncertain requests to a stronger one. This guide compares the three application-side routing patterns, separates what your application owns from what OpenRouter's Auto Router and model…
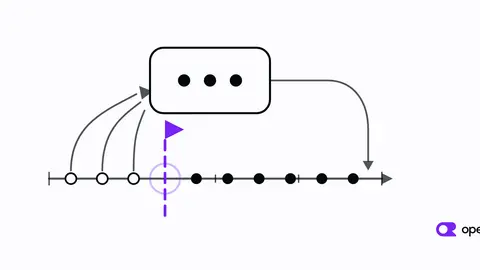
Confidence-based escalation keeps most requests on a cheap model and sends only the ones it is unsure about to a stronger one. This guide covers forcing a numeric confidence field with structured outputs, setting the threshold from error rates on your own traffic, tuning it against accuracy, cost,…
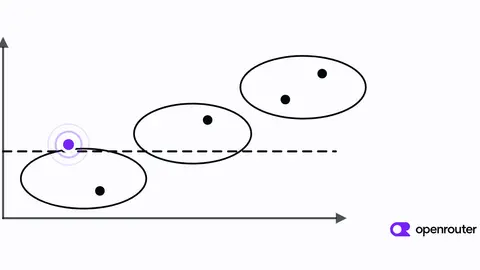
The cheapest model that clears your quality bar is usually not the model at the top of a leaderboard. This framework sets the bar for one task, measures cost per quality point across a cheap, a mid-tier, and a frontier model on your own examples, and picks the cheapest one that clears the bar with…
A one-line prompt change can ship an agent that tells customers the wrong refund window, and nothing in a normal CI pipeline checks what the model says.
An agent can call the wrong tool, or call the right tool with the wrong arguments. This guide covers three ways to test each failure mode, a Python harness that grades both, and how to run the same test cases against several tool-capable models through OpenRouter.
A golden eval dataset is a curated set of production inputs with reviewed expected outputs, versioned in Git and run before every deploy. This guide covers the five steps to build one from live traffic and how to run the same set against many candidate models through one API.
An agent's behavior can change when you edit a prompt, swap a model, change a tool schema, or change what retrieval returns. This guide covers the locked case set, the per-case behavioral contract, and how to run the same suite against two concrete model slugs through OpenRouter so the diff shows…
If you already have the image a video should start from, the model choice comes down to what has to happen after that frame. This post compares the Veo 3.1, Seedance, Kling, and Grok Imagine Video lines on duration, resolution, first-frame and last-frame control, generated audio, reference inputs,…
We audited our own OpenRouter account and found over 1,000 active API keys for 85 employees, 168 of them hadn't been used in months. The new Security Center helps you manage and de-risk your API keys with one place to see every key, know which ones are risky and why, clean them up, and lock them to…
An embedding model decides what your retrieval system can find. We shortlisted the embedding models in our catalog for English RAG, multilingual retrieval, code search, text-and-image retrieval, and low-cost indexing, sent live requests to each one, and recorded their prices, context windows, and…
A method for putting Jev to work on a new problem, worked end to end on marketplace listing moderation: what stays in code, what Jev sees, how to phrase the questions, and how to turn its probabilities into publish, hold, or reject.
Claude Opus 5 leads OpenRouter's classification task ranking by spend. We sent the same 3,080 Banking77 utterances to it and to Jev 1.13 through the Decisions API. Opus scored 84.4% to Jev's 81.0%, and Jev answered in 175 ms at $0.11 per thousand requests against 2.3 seconds and $2.42 for Opus.
Showing 18 of 32 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts