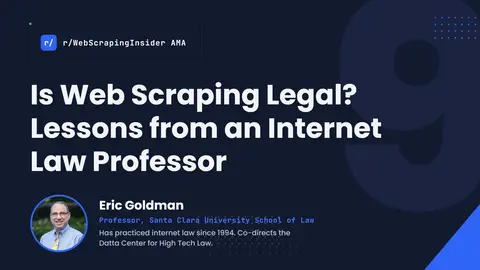
Is Web Scraping Legal? 9 Practical Lessons from Internet Law Professor Eric Goldman
An internet law professor explains how the CFAA, contracts, copyright and DMCA 1201 shape real scraping decisions about accounts, suppliers and data.
16 stories
An internet law professor explains how the CFAA, contracts, copyright and DMCA 1201 shape real scraping decisions about accounts, suppliers and data.
Why diagnosing blocks, keeping sessions consistent and choosing complexity carefully beat adding stealth, from 7 years of reverse engineering anti-bots.
Why Scrape.do skips the browser on most requests, maintains sessions for hard targets, and worries most about responses that look fine but miss data.
Inside the target-specific reputation, session management, browser identity and capacity economics that decide whether a scraper actually works.
Billions of requests through 50+ proxy providers show why the best provider changes by website, page type and volume, and what you are really paying for.
Inside the fingerprint populations, IP reputation, black-box testing and maintenance burden that decide whether a stealth browser survives production.
Inside the persistent identity, moving-target stealth and verification problems that decide whether a browser agent's actions ever add up to a finished task.
Inside the silent data failures, session trust limits, browser-context execution and repair boundaries that decide if an AI-built scraper survives production.
Why scraper detection is no longer about one bad fingerprint, but whether your fingerprint, IP, cookies and session behavior keep describing the same believable browser.
Inside the shared supply, real-time filtering and misleading metrics that determine whether a residential proxy network actually performs.
There is no universal best proxy provider. Benchmark data shows price barely predicts performance, and the winner changes by site and volume. The only way to find the best provider is to measure your own workload.
Scraping Shock is reshaping web scraping economics. As proxies get cheaper, successful scraping gets more expensive. Learn why web data is getting too expensive to scrape.
How web scraping got harder, even as proxies got cheaper. The Proxy Paradox is reshaping the economics of web scraping.
Announcing the launch of ScrapeOps, a web scraping extension that gives you all the scraping monitoring, alerting, scheduling and data validation you need straight out of the box.
What are the biggest trends and developments in web scraping? What does 2022, likely have in store for web scraping?
Today, after months of refinement with Alpha users we're really excited to annouce the launch of the ScrapeOps public Beta!
Showing 16 of 16 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts