Know a great AI tool or AI news source? Submit it to AiByts

quantization

9 stories

Stories

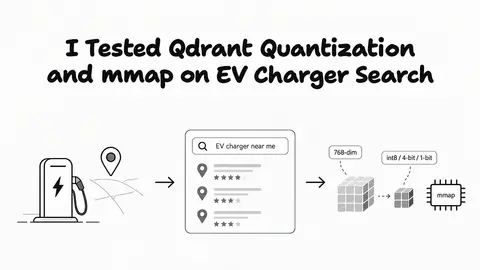
  • I Tested Qdrant Quantization and mmap on EV Charger Search

    I Tested Qdrant Quantization and mmap on EV Charger Search What got smaller, what stayed accurate, and where the memory really went When I started this project, I had a question in mind: if a …

    Towards AI21 min read
  • Bonsai 1.7B

    Bonsai 1.7B has been the quiet entry in PrismML's lineup since March, overshadowed by the flagship Bonsai 27B that made headlines for fitting a 27B-class model on an iPhone.

    Awesome Agents Newsletter Blog8 min read
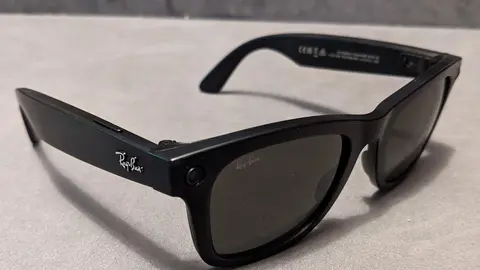
  • PrismML Puts a 1-Bit AI Model on Smart Glasses

    PrismML and Qualcomm just shipped a small technical first that matters more than the demo suggests: true binary weights, values that are either +1 or -1 and nothing else, running on a commercial NPU for the first time.

    Awesome Agents Newsletter Blog5 min read
  • 4-bit Rotational Quantization

    4-bit Rotational Quantization in Weaviate 1.39: the SIMD performance work, a centered tier, scaling analysis and a TurboQuant comparison.

    Weaviate10 min read
  • When Your Collection Outgrows RAM

    When Your Collection Outgrows RAM Once a collection no longer fits in RAM, the kernel evicts vector pages, and the next query waits on a disk read to get them back. Quantization buys that memory back.

    Qdrant11 min read
  • Lossless Inference

    How to make LLM serving faster without touching the model. Exact kernels, speculative decoding, lossless compression, KV reuse and scheduling, with the math and how to verify it with logit parity.

    RunInfra Blog8 min read
  • Bulk Uploading Data to Qdrant

    Bulk Uploading Data to Qdrant Why Bulk Uploading Matters When you start using Qdrant at scale, one of the first challenges you may run into is uploading large amounts of data efficiently. Small uploads are usually straightforward, but bulk ingestion introduces a different set of concerns.

    Qdrant8 min read
  • Optimizing AI Models with Quanto on H100 GPUs

    In this article discover Quanto a powerful quantization technique designed to optimize deep learning models without compromising the performance of the model.

    Paperspace Blog10 min read

Showing 9 of 9 stories

You're all caught up.

AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts