Best Tools for Hallucination Detection in LLMs (2026)
An LLM can return a fluent, confident answer that contains unsupported claims, contradicts the retrieved context, or invents facts. Traditional application monitoring won’t catch any...
6 stories
An LLM can return a fluent, confident answer that contains unsupported claims, contradicts the retrieved context, or invents facts. Traditional application monitoring won’t catch any...
RAG evaluation metrics with formulas and a worked example: precision@k, recall@k, MRR, nDCG, faithfulness and answer relevancy, plus why frameworks disagree.
Evaluating Retrieval-Augmented Generation (RAG) systems remains a challenge for Low-Resource Languages (LRLs), where standard reference-based metrics fall short.
An agent passes every offline eval in CI. You ship it. Production breaks within a week, because a class of prompts your eval dataset never...
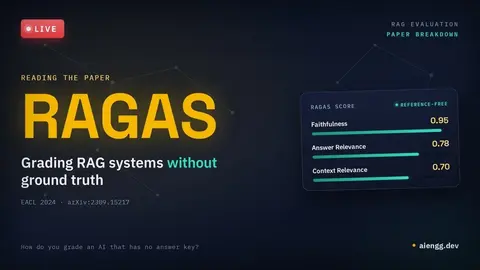
Paper: https://arxiv.org/abs/2309.15217 The AI engineering cohort starts on 12th September 2026. A focused, intense 8-week program for software engineers who want real, production-grade AI skills. 00:00 Paper Reading 26:26 AI Cohort Description Website: https://aiengg.dev/ Cheers!
Evaluation measures performance using metrics like precision, recall, and relevancy, providing a clear picture of your pipeline’s strengths and weaknesses using LLMs or ground-truth labels.
Showing 6 of 6 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts