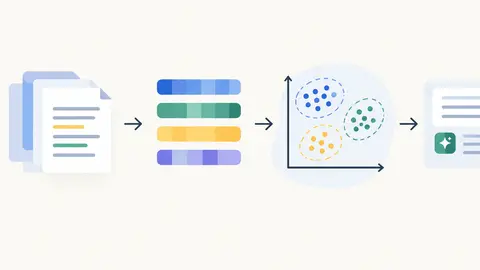
Building a RAG Pipeline with LLM Embeddings and Scikit-learn
In this article, you will learn how to build a lightweight, end-to-end RAG pipeline using scikit-learn for vector retrieval and open-source models for embeddings and...
29 stories
In this article, you will learn how to build a lightweight, end-to-end RAG pipeline using scikit-learn for vector retrieval and open-source models for embeddings and...
A practical guide to strengthening churn, CLV, and other traditional models with text The post How to Leverage NLP for Product Data Science appeared first on Towards Data Science.
A local embedding model turns your text into vectors on hardware you control, so no document or query leaves your machine to get embedded.
Explore 10 Hugging Face models used across text, vision, audio, and retrieval in 2026.
EmbeddingGemma 2 launched on October 6, 2026 under Apache 2.0. It is a sub-1B model built on Gemma 4 that maps text, code, images, video and audio into one 768-dimensional space. This article covers the architecture, the benchmarks, and runnable scripts to provide measured results.
Sparse neural retrieval finally started getting more and more attention (SPARSEUP, MILCO, sparse encoders in Sentence Transformers…). Well, amazing, we like attention!
pplx-embed-v2-late has no public API price yet. See current Perplexity embedding rates and a practical multimodal PDF retrieval setup.
Plan an EmbeddingGemma 2 local deployment without corrupting retrieval. Compare runtimes, rebuild risk, vector dimensions, and mixed-modal quality.
Google's EmbeddingGemma 2 maps text, images, video, and audio into one 768-dim vector space under Apache 2.0. Here's how it actually works.
EmbeddingGemma 2 API explained: local deployment, multimodal embedding support, model size, vector dimensions, and practical use cases.
Reduce costs, improve response quality, and build leaner AI applications with these prompt engineering strategies.
As of 26 September 2026, the best open-source embedding model for most teams is Qwen3-Embedding, which is Apache 2.0, reads 32K tokens and ranks 5th on MTEB English v2 and 4th on MTEB Multilingual v2.
In this article, you will learn what embedding drift is, why it matters for production large language models, and how to implement two practical techniques...
In this article, you will learn how a vector database works under the hood by building one from scratch in ten incremental steps using Python...
Simple RAG example on the Oscars using Llama 3.1 open models and the Haystack LLM framework. Installation ! pip install transformers-haystack sentence-transformers-haystack bitsandbytes Authorization you need an Hugging Face account you need to accept Meta conditions here:…
Evaluating the responses of Language Models and LLM-based applications often involves using model-based metrics that do not require ground truth labels.
We introduce NeoMME, a family of 260M and 800M multilingual multimodal encoders. Unlike many generative visual language models, NeoMME does not use a separate pretrained vision tower or a causal language model.
Level: Advanced Time to complete: 20 minutes Components Used: InMemoryDocumentStore, SentenceTransformersDocumentEmbedder, SentenceTransformersTextEmbedder, InMemoryEmbeddingRetriever, ChatPromptBuilder, OpenAIChatGenerator, Agent Prerequisites: You must have an OpenAI API Key and be familiar with…
Showing 18 of 29 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts