
Granite 4.2 LLMs: How They're Built
TL;DR: Granite 4.2 is our first family of dense, decoder-only reasoning LLMs, released in three sizes: 3B, 8B, and 30B. These models are post-trained from Granite-4.1 base models.
Hugging Face Blog21 min read
29 stories
TL;DR: Granite 4.2 is our first family of dense, decoder-only reasoning LLMs, released in three sizes: 3B, 8B, and 30B. These models are post-trained from Granite-4.1 base models.
Alibaba finally opened a Max-class Qwen — and the 2.4T checkpoint downloads at 4.89 TB, three times Kimi K3 for a smaller model, because Qwen shipped BF16 where Moonshot shipped pre-quantized 4-bit.
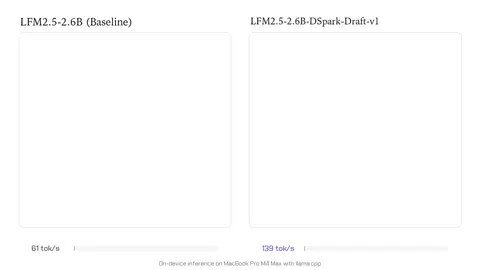
Today, we release DSpark draft model checkpoints for three models from our LFM2.5 family: LFM2.5-1.2B-Instruct, LFM2.5-2.6B, and LFM2.5-8B-A1B. These add a speculative decoding path that trades a minimal memory increase for a large decoding speedup without changing output quality:
Stock SGLang served gpt-oss-120b at 411 tokens per second on one rented B200. Four settings took the same card and the same weights to 1,366, and single prompts to 2,215. No kernel written, nothing recompiled.
Moonshot released Kimi K3's weights on July 27, 2026. What that actually gets you at 2.8 trillion parameters — the real download size, the hardware floor, the bespoke license, and how to choose between self-hosting, the official API, and an aggregator.
ThunderAgent is a program-aware scheduler for agentic inference. By treating each agent workflow as a schedulable program, it eliminates KV cache thrashing to deliver more than 2x single-node throughput and near-linear multi-node scaling.
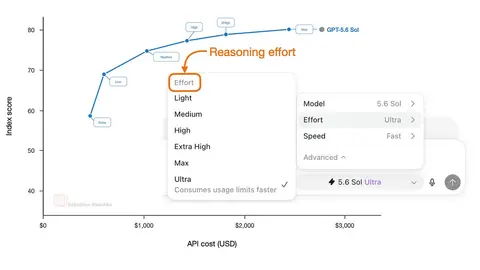
How LLMs Learn Low-, Medium-, and High-Effort Reasoning Modes
At @fal , we've achieved 16 times higher throughput on Qwen3.6 for a use-case that required high interactivity per user using DSpark on SGLang. But why did we need it? And how did we achieve it?IntroText-to-image models like Ideogram V4 can generate stunning,
Self-reported Llama-3.1-8B results for three LLM inference engines. Published unique-prompt throughput and latency rows cover H100 bf16. FP8 and L40S appear only in derived cost results. The harness and raw data are not publicly available.
The most powerful AI platform for enterprises. Customize, fine-tune, and deploy AI assistants, autonomous agents, and multimodal AI with open models.
A technical look at LLaMA Factory—a feature-rich toolkit for tuning large language models—and the latest updates through 2025.
Showing 29 of 29 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts