
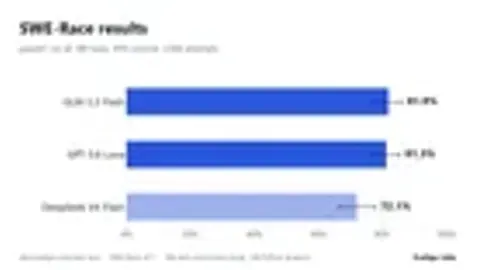
SWE-Race: a coding-agent benchmark of 188 real concurrency bugs, with results from three models [P]
We've been building a benchmark out of real concurrency bugs (race conditions, deadlocks, cancellation issues) taken from merged PRs in about 100 Python projects.
Reddit - r/ML2 min read