
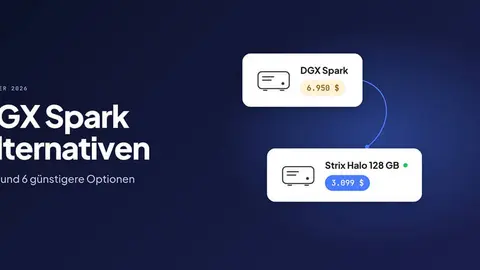
DGX Spark Alternativen 2026: Preis und 6 günstigere Optionen
DGX Spark kostet jetzt 6.950 US-Dollar. Preis in Deutschland, wo kaufen und 6 günstigere Alternativen: von Ollama gratis bis Strix-Halo-Mini-PC.
BetterClaw Blog29 min read
12 stories
DGX Spark kostet jetzt 6.950 US-Dollar. Preis in Deutschland, wo kaufen und 6 günstigere Alternativen: von Ollama gratis bis Strix-Halo-Mini-PC.
Hybrid models interleave state-space model (SSM) layers with a few attention layers. NVIDIA Nemotron 3, Qwen3.5 through Qwen3.8, Kimi-K3, and GLM-5.3-Flash are...
A 90-day architectural blueprint for scaling from prototype to mission-critical availability.
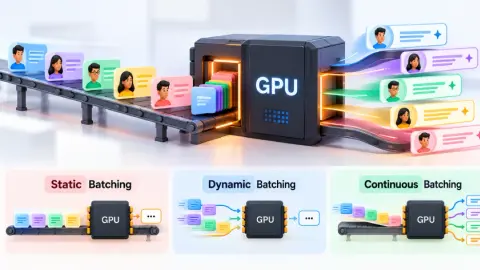
Imagine four people booking a ride to the same destination. If each person takes a separate taxi, four vehicles make the same trip. But if they travel together in a bus, everyone reaches the destination in a single trip. The bus carries more people at once and makes better use of the resources.
Learn how vLLM achieves higher throughput than Hugging Face Transformers by using PagedAttention to eliminate memory waste, boost inference.
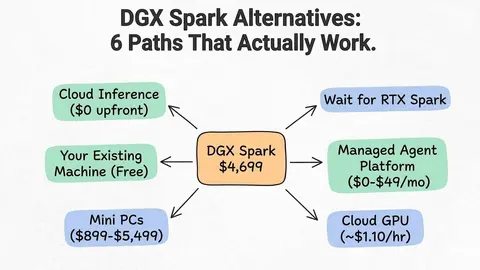
DGX Spark now costs $6,950 and runs Linux only. Six cheaper alternatives ranked by price, from free Ollama and cloud APIs to Strix Halo PCs and Mac Studio M5.
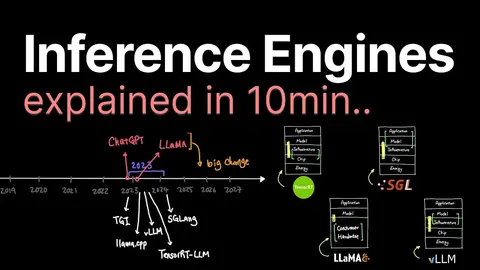
Try Zapier: https://bit.ly/4yVvOtV Zapier helps you build custom automation and we're looking at how Zapier CLI can help me build news scanner app that keeps me up to date with AI.
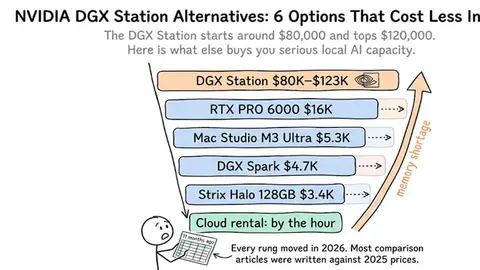
DGX Station price, Sept 2026: no NVIDIA list price. OEM listings run $91,813 (Supermicro) to $99,999 (MSI). What quotes include, and 6 cheaper options.
Learn how to run vLLM on Runpod’s serverless GPU platform. This guide walks you through fast, efficient LLM inference without complex setup.
As large language model (LLM) inference increasingly processes sensitive information and proprietary model context across personal, enterprise, and regulated...
AI agents are moving from cloud data centers to vehicles, robots, and other edge devices. Unlike a chatbot that answers a single prompt, an agent works through...
Self-reported Llama-3.1-8B results for three LLM inference engines. Published unique-prompt throughput and latency rows cover H100 bf16. FP8 and L40S appear only in derived cost results. The harness and raw data are not publicly available.
Showing 12 of 12 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts