
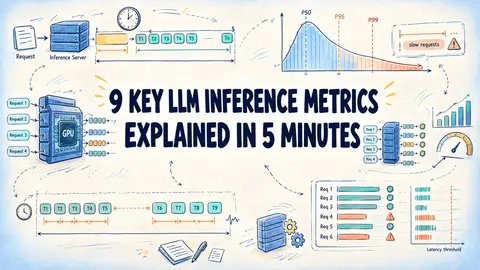
9 Key LLM Inference Metrics Explained in 5 Minutes
Learn how to measure LLM inference performance using key metrics and formulas for latency, token generation speed, and system load.
KDnuggets9 min read
2 stories
Learn how to measure LLM inference performance using key metrics and formulas for latency, token generation speed, and system load.
AI inference in plain English: how a prompt becomes an answer on a GPU, why tokens keep getting cheaper, and how a team can judge AI tools by cost per task.
Showing 2 of 2 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts