NVIDIA Run:ai Is Now Open Source as Part of NVIDIA DSX AI Factory Platform
NVIDIA is making the full NVIDIA Run:ai platform available as open source software, giving customers, developers, and ecosystem partners access to...
239 stories
NVIDIA is making the full NVIDIA Run:ai platform available as open source software, giving customers, developers, and ecosystem partners access to...
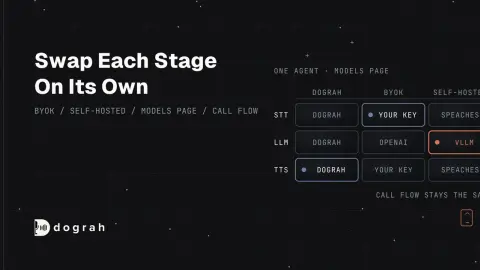
Follow one caller's sentence through speech-to-text, the language model and text-to-speech, with where the time goes at each stage and what breaks between them.
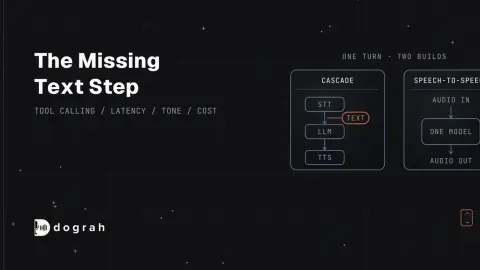
How cascade and speech-to-speech voice agents compare on tool calling, latency, voice and cost in 2026 benchmarks, and how to choose per agent.
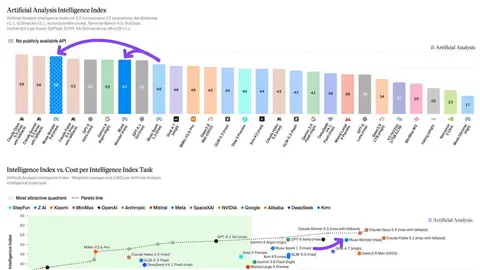
We have been coveringe MSL’s 14 month journey to becoming a frontier lab, but only today did the final ball drop: Meta’s Muse Wonder to match Spark and Glimmer, the way that OpenAI has Sol/Terra/Luna and Anthropic has Opus/Sonnet/Haiku.
I’ve watched AI-powered cyberattacks inch closer to autonomy throughout 2026, and I can point to dozens of real-world incidents as proof. AI-enabled cyberattacks surged by 56% over the last year, meaning 1 in 4 (25%) malicious breaches now involve artificial intelligence.
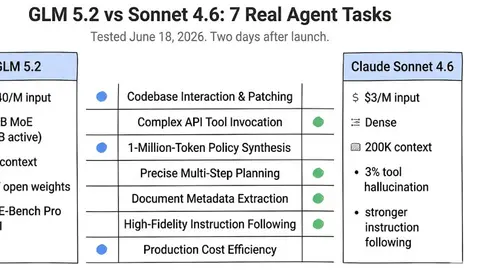
GLM 5.2 vs Sonnet 4.6 on seven real agent tasks, updated for GLM 5.3 and Sonnet 5 with verified prices and a GLM 5.1 lineage note.
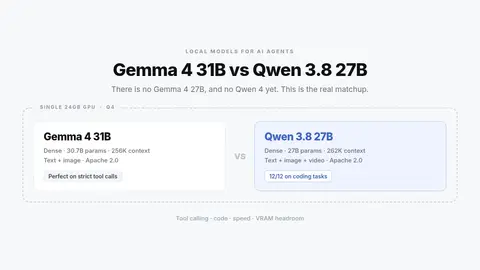
Searching for Gemma 4 27B or Qwen 4 27B? Neither exists yet. The real matchup is Gemma 4 31B vs Qwen 3.8 27B: tool calling, code, speed and VRAM on a 24GB card.
Can Strata's local AI engine run on a single RTX 3060 12GB? Here's the hardware cost breakdown, performance numbers, and Hermes agent setup.
A local embedding model turns your text into vectors on hardware you control, so no document or query leaves your machine to get embedded.
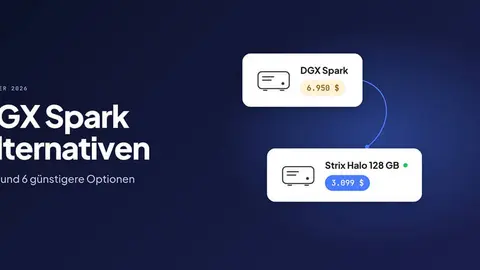
DGX Spark kostet jetzt 6.950 US-Dollar. Preis in Deutschland, wo kaufen und 6 günstigere Alternativen: von Ollama gratis bis Strix-Halo-Mini-PC.
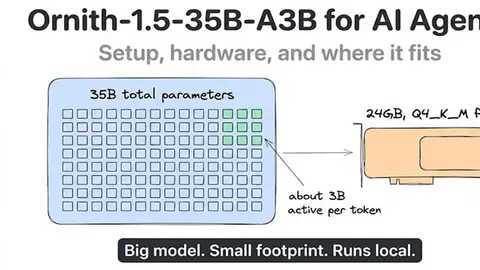
Ornith-1.5-35B-A3B: a 35B MoE with 3B active. Ollama run command, hardware by quant, OpenClaw setup, and benchmarks vs Qwen3.6 and Qwen3.5.
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
Article URL: https://www.intel.com/content/www/us/en/products/details/discrete-gpus/data-center-gpu/d-series.html Comments URL: https://news.ycombinator.com/item?id=50063365 Points: 48 # Comments: 17
If you run a Kubernetes platform, you’ve probably got at least one Grafana dashboard for resource visibility on your workloads. The post GPUs on Kubernetes are bring-your-own-everything, starting with the bill appeared first on The New Stack.
Hybrid models interleave state-space model (SSM) layers with a few attention layers. NVIDIA Nemotron 3, Qwen3.5 through Qwen3.8, Kimi-K3, and GLM-5.3-Flash are...
Learn how to deploy decision models with llama.cpp on Amazon SageMaker AI. This technical how-to serves OpenAI-compatible chat completions with the AWS Deep Learning Container for llama.cpp, then extends the runtime with SemIf to return probabilities over declared options on CPU or GPU.
Learn how to deploy one large language model across two GPU nodes on Amazon EKS using the multi-node Ray LLM Deep Learning Containers, with separate prefill and decode nodes behind one OpenAI-compatible endpoint.
A 90-day architectural blueprint for scaling from prototype to mission-critical availability.
Showing 36 of 239 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts