
Holo4 27B vs 35B-A3B: Which Fits Your Agent?
Holo4 27B vs 35B-A3B compares long-task reliability, task economics, and weight licenses so builders can choose an agent model.
WaveSpeed Blog5 min read
244 stories
Holo4 27B vs 35B-A3B compares long-task reliability, task economics, and weight licenses so builders can choose an agent model.
Issue #4 of The State of Serene: faster search on every core and from a cold cache, regex and fuzzy search that always answer, text analyzers as expressions, HNSW, the docs inside the binary, OpenTelemetry ingestion, faster time histograms, MATCH_RECOGNIZE, spatial and AI functions.
KV cache explained: what it stores, a per-model memory table from 8K to 128K context, and the Ollama, llama.cpp, LM Studio and vLLM settings that shrink it.
ds4 runs big MoE models on 96 GB Macs, Magnitude tunes kernels to your device, Strata puts one model on a gaming PC. Every speed claim is self-reported.
Kolibri is an English-German Mixture-of-Experts model with 78B total and 3B active parameters, a context of up to 1M tokens and open weights under Apache 2.0, specialized for sovereign, mission-critical work.
Developers are skeptical by default, and that is a good thing when choosing a Gen-AI course. Here is a technical checklist to score any online GenAI course before you enrol. The scoring checklist Give each item 1 point. A strong course should score 10 or more out of 12.
Kolibri-1 needs roughly 78GB of FP8 weights and multi-GPU setups to serve. Here's the full vLLM, VRAM, and hardware guide.
Kolibri-1 is Aleph Alpha's 78B MoE model with 3.46B active params. Here's what hardware you need and how to serve it with vLLM.
Kolibri-1 is Aleph Alpha's 78B MoE model with 3.5B active params, 1M context, and Apache 2.0 license, built for German and English.
AI News for 10/1/2026-10/2/2026. We checked 12 subreddits, 544 Twitters and no further Discords. AINews’ website lets you search all past issues. As a reminder, AINews is now a section of Latent Space. You can opt in/out of email frequencies!
Parece cena de ficção científica: uma cancela de pedágio aos pés da pirâmide da Tyrell Corp cobrando uma taxa por cada bit do seu código. Daria pra chamar de "imposto de token" essa tentativa de criar um lock-in onde três ou quatro fornecedores de IA precificam cada linha de código que o seu time…
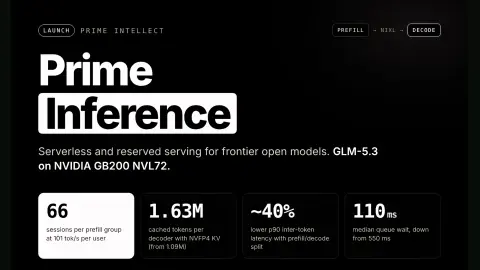
Prime Intellect has launched Prime Inference, an OpenAI-compatible platform for serving frontier open models on NVIDIA Blackwell. Its GLM-5.3 deployment uses Dynamo, vLLM and NVFP4 KV compression to serve 66 sessions per prefill group at 101 tok/s per user.
IQuest-Q1 is a 320B MoE model with 15B active params and 512K context, designed for agentic coding with Claude Code and Codex CLI.
IQuest-Q1 is a 320B MoE coding model with 15B active params and 512K context. Here's what it takes to run it with SGLang or vLLM.
A local test of Limit 1B Violetto, Paradigma's 1B math specialist, covering install steps, VRAM use, and its tendency to drift off-topic.
Learn how to deploy OpenJev, a 27B structured-decision model, on a Runpod Serverless load balancer endpoint, then send requests with cURL and Python.
TL;DR We integrated Helion into vLLM’s linear backend to explore how an autotuned, high-level kernel DSL can improve LLM inference performance while reducing kernel implementation complexity. A single Helion general...
Run AstaBrief 8B with vLLM and connect it to a private PDF retrieval pipeline, with citation IDs, prompt format, and validation steps.
Showing 108 of 244 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts