
Write Like It's 1866: LLMs Relearn Telegraphese
Article URL: https://fiveminutesforward.com/post/2026-10-04-telegraph-test/ Comments URL: https://news.ycombinator.com/item?id=49991580 Points: 16 # Comments: 7
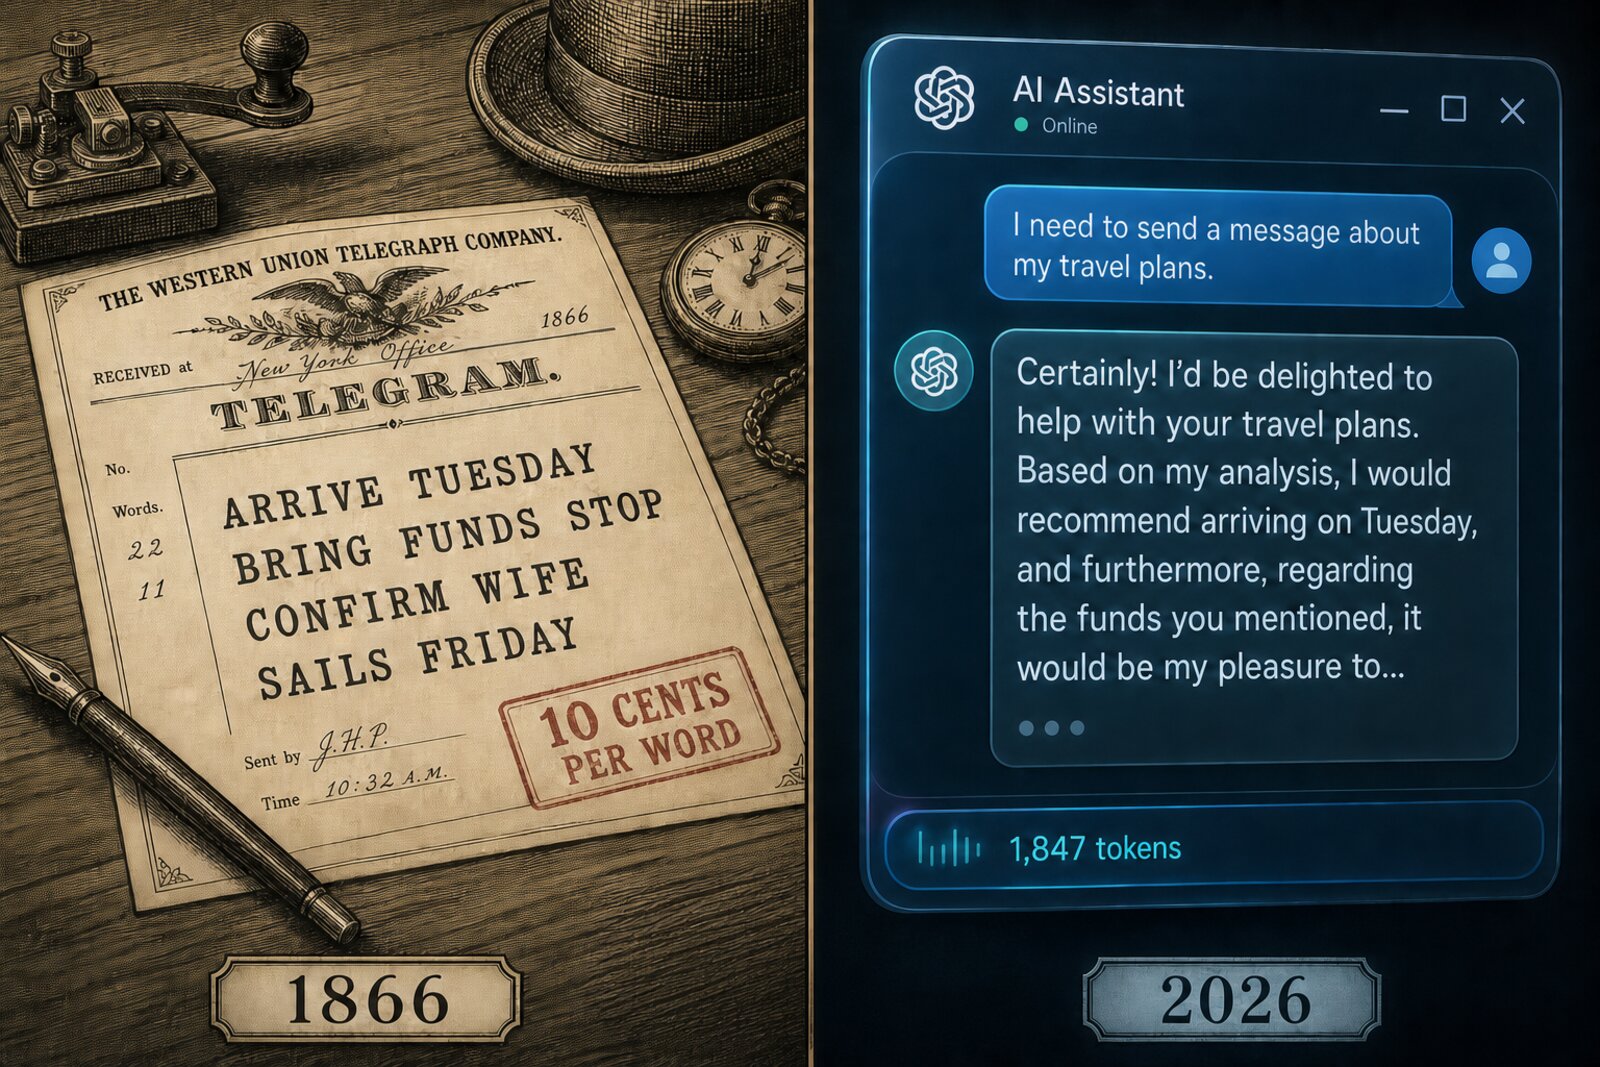
The article discusses a method of compressing large language model (LLM) outputs using a telegraph-style format called 'cablese' to reduce token usage and costs, with experiments showing significant efficiency gains across various models.
What happened
The article presents a method of compressing LLM outputs using a telegraph-style format called 'cablese' to reduce token usage and costs. Experiments show that models can generate and read cablese records with high accuracy, achieving significant token savings without compromising comprehension.
Why it matters
This method offers a practical way to reduce LLM costs and improve efficiency, particularly for machine-to-machine communication and storage. It allows for more context in agent memory and reduces the financial burden of API usage without requiring additional training or hardware.
- Cablese compression can reduce token usage by 25-49% across various LLMs.
- Models can read and understand cablese records as effectively as plaintext, making it suitable for machine consumption.
- Compression is most effective when applied after content is finalized, avoiding additional reasoning costs.
- The method requires no training or hardware changes, only a simple instruction to the model.
- Cablese is human-readable and auditable, making it suitable for use in agent-to-agent communication and memory storage.
The bigger picture
The technique enables significant cost savings for LLM usage, particularly in scenarios involving machine-to-machine communication and storage. It allows for more efficient use of context in agent memory and reduces the financial impact of API calls without requiring changes to existing models or infrastructure.
The article demonstrates that using a telegraph-style compression format called 'cablese' can significantly reduce LLM token usage and costs. This method allows for efficient machine-to-machine communication and storage, with high accuracy and minimal setup, offering a practical solution for optimizing LLM usage.
Technical details
- Cablese: A compressed, telegraph-style format that uses lowercase, abbreviations, and removes articles and filler words.
- Recovery ratio: A metric comparing the accuracy of models answering questions from compressed records versus plaintext, with 1.00 indicating parity.
- Token savings: The percentage reduction in tokens when using cablese compared to plaintext.
- Cross-family matrix: A comparison of different models' performance in reading and writing cablese records.
- Deterministic grading: A method of evaluating answers based on fixed string matching without human judgment.
FAQ
What is cablese?
Cablese is a telegraph-style compression format that uses lowercase, abbreviations, and removes articles and filler words to reduce token usage while maintaining readability and comprehension.
How much token savings can be achieved with cablese?
Cablese can reduce token usage by 25-49% across different LLMs, depending on the model and the specific implementation.
Does using cablese affect the accuracy of LLMs?
No, models can read and understand cablese records as effectively as plaintext, with recovery ratios of 0.99-1.10, indicating high accuracy.
Is any training or hardware changes required to use cablese?
No, the technique requires no training or hardware changes, only a simple instruction to the model to generate and read cablese records.
What are the benefits of using cablese for LLMs?
Cablese reduces token usage and costs, improves efficiency for machine-to-machine communication, allows for more context in agent memory, and is human-readable and auditable.
This summary and analysis were generated with AI from the original article and may contain errors. Read the original for the full story.
Read the full story
Originally published by Hacker News on Oct 7, 2026.
Comments
Sign in to join the discussion.