
Together AI
Full-stack AI platform for inference, fine-tuning, and GPU clusters.
What is Together AI?
Together AI is an AI Platforms tool. Full-stack AI platform for inference, fine-tuning, and GPU clusters. Together AI is freemium: it has a free plan plus paid upgrades. It is aimed at developers and ai researchers.
Build what's next on the AI Native Cloud. Full-stack AI platform for inference, fine-tuning, and GPU clusters — powered by cutting-edge research.
Built for developers and ai researchers.
Key capabilities
Features
Full-Stack Cloud
Research-Backed
Built on cutting-edge research for AI development.
AI Native Development
Use cases
- Train AI models at production scale
- Fine-tune AI models for specific tasks
- Run inference on AI models efficiently
Who it's for
Pros & cons
Pros
- Public API available
Cons
- Free plan not shown on pricing page
Pricing
Freemium.
| Plan | Price |
|---|---|
| Chat, vision, embeddings, rerank (per token) | $0 |
| Image generation (per image) | $0 |
| Video generation (per video) | $0.14 |
| Audio transcription (per minute) | $0 |
| On-demand (hourly) | $5.49 |
| Reserved (7–180+ days) | $3.99 |
| Code Sandbox — RAM | $0.01 |
| Code Sandbox — vCPU | $0.04 |
| Code Interpreter — per session (60 min) | $0.03 |
| Standard pricing | $0.48 |
AI models
- Kling 1.6
- Veo 2.0
- Hailuo 02
- Seedance 2.5
- Wan 2.6
- Imagen 4
- FLUX
- Seedream 4.0
- Nano Banana Pro
- GPT 5
- Gemini 3 Pro
- Llama 4
- Mistral 8x7B
- DeepSeek V4
- Qwen 3.5
Developer & API
Public API available
Security & compliance
- SSO
- Data deletion
As stated on Together AI's website — not independently verified by AiByts.
FAQ
What is Together AI?
Together AI is an AI Platforms tool. Full-stack AI platform for inference, fine-tuning, and GPU clusters. Build what's next on the AI Native Cloud. Full-stack AI platform for inference, fine-tuning, and GPU clusters — powered by cutting-edge research.
Is Together AI free?
Together AI has a free plan; advanced features require a paid plan.
How much does Together AI cost?
Together AI offers 10 plans: Chat, vision, embeddings, rerank (per token) ($0), Image generation (per image) ($0), Video generation (per video) ($0.14), Audio transcription (per minute) ($0), On-demand (hourly) ($5.49) and Reserved (7–180+ days) ($3.99).
Does Together AI have an API?
Yes, Together AI offers a public API for building custom integrations.
Who should use Together AI?
Together AI is built for developers and ai researchers. Common uses: train AI models at production scale, fine-tune AI models for specific tasks and run inference on AI models efficiently.
What are the best alternatives to Together AI?
Similar tools on AiByts include DataRobot, Generrated, Hebbia, Weights and Biases Weave and Viso Now.
Together AI news & updates
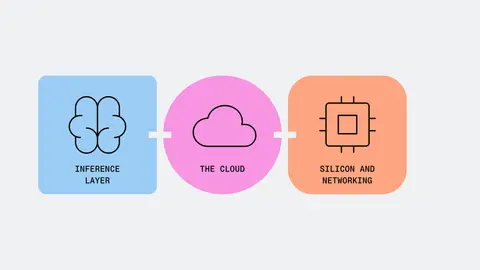
Expanding our enterprise inference capacity with IBM Cloud and NVIDIA
Enterprises can now run open models at production scale on a dedicated B300 inference cluster, built by Together AI, IBM Cloud, and NVIDIA
Together AI Blog2 min read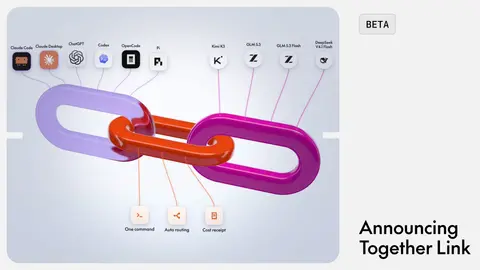
Together Link: open models in the harness you already use. Start with one command today.
Together Link brings frontier open models like GLM 5.3 and Kimi K3 into the coding agent your team already uses, cutting model spend by over 50%.
Together AI Blog3 min read
How to train your own Jev for $17
We just launched our own Jev-like classifier, together/Tev1-4B-experimental, on top of Qwen3.5 4B on Together’s serverless platform. In this blog post we’ll show you how to fine-tune your own version!
Together AI Blog8 min read
Canary rollouts: upgrade models in production without downtime
A hard model swap exposes every user at once, and rolling back means cold-starting the old deployment under pressure. Here's how staged traffic ramps, metric gates, and automatic rollback work on dedicated inference.
Together AI Blog19 min read
How a global fintech scaled coding agent traffic with Dedicated Model Inference
Inside a global bank's shift to self-serve dedicated inference: how Together's DMI gave engineering teams direct control over scaling, models, and testing.
Together AI Blog7 min read
Migrating from closed to open source models, Together
Moving from closed to open source models can take weeks, not years. A five-stage playbook: discover, evaluate, adapt, decide, and production.
Together AI Blog9 min read
Together AI expands fine-tuning service with more models, live metrics, and finer controls
Together Fine-Tuning adds the latest open-weight models, live experiment tracking, Expert LoRA, early stopping, tokenized dataset previews, pre-flight validation, and lower training prices on selected models.
Together AI Blog10 min read
To Infinity and Beyond: ThunderKittens Now on NVIDIA Vera Rubin NVL72!
We ported ThunderKittens to NVIDIA's Vera Rubin NVL72 and rebuilt our NVFP4 GEMM around the new hardware, taking it from 42% of roofline to over 22 PFLOPS — competitive with cuBLAS and CuTe DSL. Here is what changed in the ISA and how we used it.
Together AI Blog10 min read
Introducing preemptible compute: the same compute, half the price
Together GPU Clusters now supports preemptible compute: the same GPU capacity at a flat 50% of the on-demand rate, with a five-minute drain window.
Together AI Blog4 min read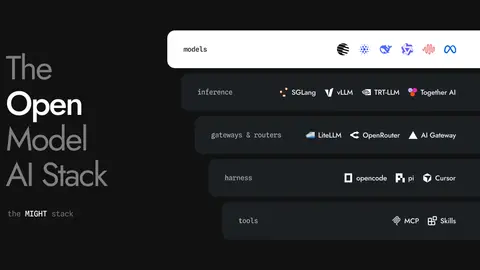
The Open Source AI Stack
A deep dive into the open model AI stack — model, inference, gateways and routers, harness, and tools — and how keeping each layer independent lets you swap in a new open model in minutes instead of rebuilding your workflow.
Together AI Blog14 min read
GLM-5.3 vs. GLM-5.3 Flash on DeepSWE: Cost, Coding, and Routing
We ran 900 DeepSWE rollouts on GLM-5.3 and GLM-5.3 Flash. Flash gives up 5.6 points of pass@1 at 17x lower cost, and only 2.6 points at pass@4.
Together AI Blog12 min read
GLM-5.3 vs. Claude Fable 5 on DeepSWE: Cost, Coding, and Routing
We ran 904 DeepSWE rollouts on GLM-5.3 and Claude Fable 5. A tie on pass@1, but GLM-5.3 wins pass@4 and costs 5.4x less: \$3.99 per rollout vs. \$21.63.
Together AI Blog10 min read
GLM-5.3 vs. GPT-5.6 Sol on DeepSWE: Cost, Coding, and Routing
We ran 904 DeepSWE rollouts on GLM-5.3 and GPT-5.6 Sol. Sol leads pass@1 by 3.7 points; GLM-5.3 wins pass@4 at half the cost, and a GLM-first cascade hits 85.9%.
Together AI Blog10 min read
DeepSeek V4 Pro 0813 vs GPT-5.6 Sol on DeepSWE: Cost, Coding, and Routing
We ran 904 DeepSWE rollouts on DeepSeek V4 Pro 0813 and GPT-5.6 Sol. Sol leads pass@1 by 10 points at 35x the cost; Pro wins pass@4, and a Pro-first cascade hits 83.0%.
Together AI Blog8 min read
DeepSeek V4 Pro 0813 vs Claude Fable 5 on DeepSWE: Cost, Coding, and Routing
We ran 904 DeepSWE rollouts on DeepSeek V4 Pro 0813 and Claude Fable 5. Fable leads pass@1 at 90x the cost; Pro wins pass@4, and a Pro-first cascade hits 82.7%.
Together AI Blog8 min read
A/B test models in production
Shadow traffic proves a candidate is operationally sound. It can't tell you if users like it better. Run the split at the endpoint instead of in your app code.
Together AI Blog9 min read
DeepSeek-V4 Flash 0731 vs GPT-5.6 Luna on DeepSWE: Cost and Coding
We ran 900 DeepSWE rollouts on DeepSeek-V4 Flash and GPT-5.6 Luna. Luna leads pass@1 by 14 points; DeepSeek delivers 4.8x the solves per dollar.
Together AI Blog9 min read
Kimi K3: the complete developer guide
Kimi K3 is the first open 3T-class model. See how it benchmarks, what it costs, and how to call it on the Together AI API, with copy-paste code examples.
Together AI Blog13 min read
Details are compiled from Together AI's website and public sources, last verified Oct 3, 2026. Features and pricing change — confirm on the official site before you buy.
Try Together AI
Freemium
Comments
Sign in to join the discussion.