Know a great AI tool or AI news source? Submit it to AiByts

Arize AI

Stay updated with the latest developments in Artificial Intelligence

Latest AI News

  • Cost Agent: find where your LLM and agent spend goes with your traces

    AI costs don’t always scale predictably with traffic. A retry loop, oversized context window, or unnecessarily expensive model can make a small number of traces disproportionately expensive. The post Cost Agent: find where your LLM and agent spend goes with your traces appeared first on Arize AI.

    Arize AI4 min read
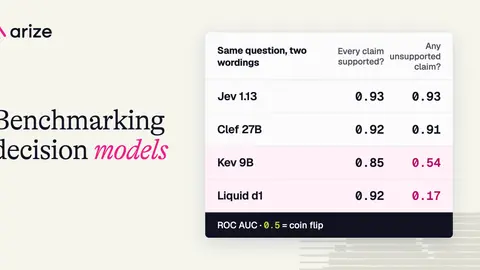
  • Decision model benchmark: Jev, Kev, Liquid d1, and more

    On 15 September, TypeSafe released Jev, and within a few weeks about 10 companies had shipped something that works the same way. OpenAI, Liquid, Cloudflare, AWS and PostHog all launched one, and an open clone called Kev showed up on Hugging Face in between.

    Arize AI14 min read
  • What agent traces can tell you without an LLM judge

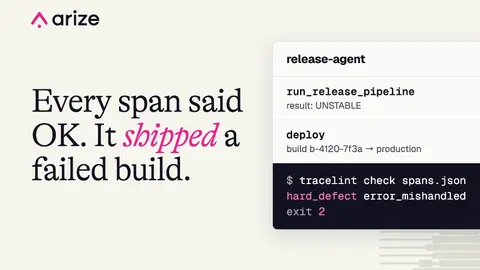
    Some agent failures are already in the trace. tracelint proves them on Phoenix OpenInference spans and fails CI, without an LLM judge. The post What agent traces can tell you without an LLM judge appeared first on Arize AI.

    Arize AI7 min read
  • Claude’s hillclimb loop for AI agents: start with production traces

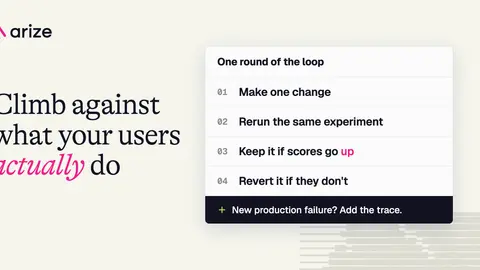
    Anthropic's Claude hillclimb loop designs evals and improves agents one change at a time. Here's how to run that loop against production traces in Arize AX. The post Claude’s hillclimb loop for AI agents: start with production traces appeared first on Arize AI.

    Arize AI12 min read
  • Alyx now remembers your work across sessions with long-term memory

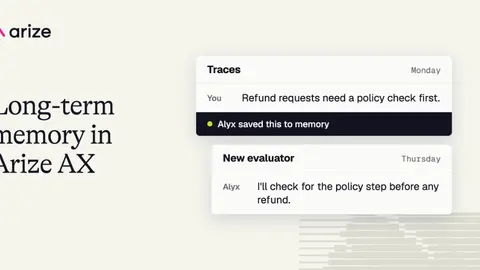
    Alyx now remembers project goals, conventions, and decisions across sessions in Arize AX, helping you continue work on traces, evals, and experiments. The post Alyx now remembers your work across sessions with long-term memory appeared first on Arize AI.

    Arize AI4 min read
  • Are agent harnesses dying? What harness distillation changes

    Harness distillation can train general scaffolding into a model. The harness that remains is the part tied to your tools, data, users, and environment. The post Are agent harnesses dying? What harness distillation changes appeared first on Arize AI.

    Arize AI9 min read
  • Anthropic says it fixed Claude’s writing. I ran the evals to check.

    Opus 5.5 dropped em dashes from 12.9 per 1,000 words to two in 57,000 words, and cut the rest of the Claudisms in half. Better, but not fixed. The post Anthropic says it fixed Claude’s writing. I ran the evals to check. appeared first on Arize AI.

    Arize AI11 min read
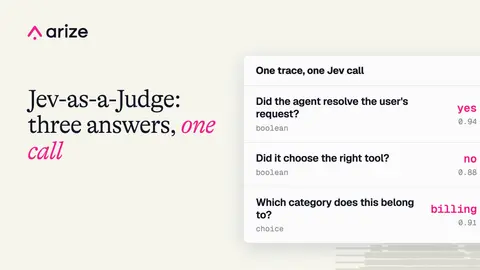
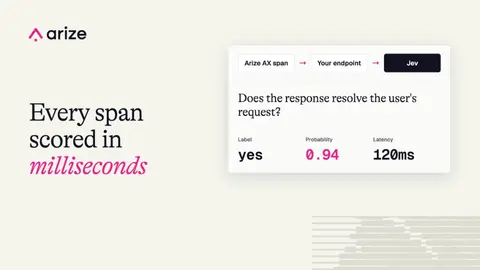
  • Evaluate production traces with Jev-as-a-Judge directly in Arize AX

    Arize AX now integrates directly with TypeSafe AI, bringing native Jev-as-a-Judge evaluations into the Arize evaluation workflow. The post Evaluate production traces with Jev-as-a-Judge directly in Arize AX appeared first on Arize AI.

    Arize AI3 min read
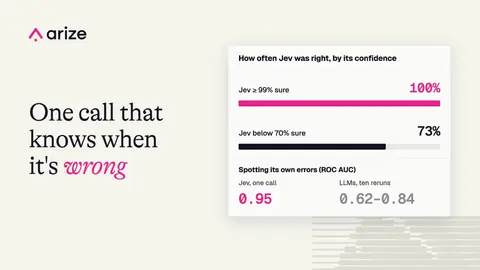
  • What Jev’s probabilities reveal that repeated LLM judgments miss

    I tested Jev and five LLM judges across ten Arize Phoenix evaluators to measure how often their answers changed alongside accuracy, cost, and latency. The post What Jev’s probabilities reveal that repeated LLM judgments miss appeared first on Arize AI.

    Arize AI12 min read
  • How we built UI Code Mode into Arize Phoenix

    We replaced the 58 tools PXI used to drive the Phoenix UI with two tools and a JavaScript sandbox that runs in your browser tab. Here's why, how it works, and what it cost. The post How we built UI Code Mode into Arize Phoenix appeared first on Arize AI.

    Arize AI22 min read
  • How to build a remote evaluator in Arize AX with Jev

    Evaluate agent responses with Jev and Arize AX. Build a FastAPI remote evaluator, return labels and scores, and choose a threshold for your data. The post How to build a remote evaluator in Arize AX with Jev appeared first on Arize AI.

    Arize AI10 min read
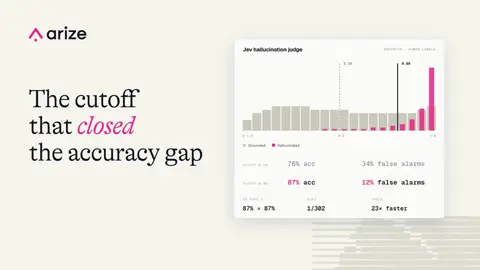
  • Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks

    We benchmarked Jev against Claude Opus 5 and GPT-5.6 Terra on accuracy, cost, and latency. Learn how threshold tuning changes hallucination detection. The post Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks appeared first on Arize AI.

    Arize AI10 min read
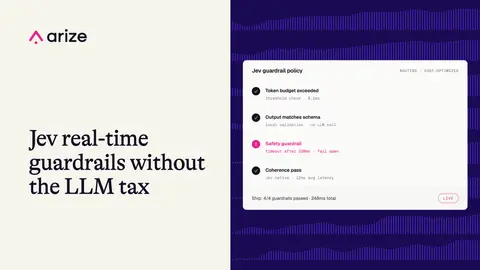
  • Real-time LLM guardrails with Jev: comparing latency and cost

    Compare Jev and GPT-5.4 nano for real-time LLM guardrails, with demo results on latency, cost, and checks on agent inputs, replies, and tool calls. The post Real-time LLM guardrails with Jev: comparing latency and cost appeared first on Arize AI.

    Arize AI11 min read
  • What changes when AI agents use your software

    Daytona cofounder Ivan Burazin wants agents that can finish the job within the authority they have been given. His interview offers a starting point for examining how agents use your software. The post What changes when AI agents use your software appeared first on Arize AI.

    Arize AI8 min read

Showing 18 of 19 stories

Load more stories
AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news from Arize AI

Join 15,000+ AI enthusiasts