AI harness crash course
The model can write the code. It can't open your files, run your tests, or ask before doing something risky. The software that does all of that is the AI harness, and this crash course shows you how to design one.
30 stories
The model can write the code. It can't open your files, run your tests, or ask before doing something risky. The software that does all of that is the AI harness, and this crash course shows you how to design one.
Learn how agent traces, human oversight, production evaluations, and log retention support EU AI Act compliance with a practical credit-assistant example. The post EU AI Act compliance for AI agents: a practical engineering guide appeared first on Arize AI.
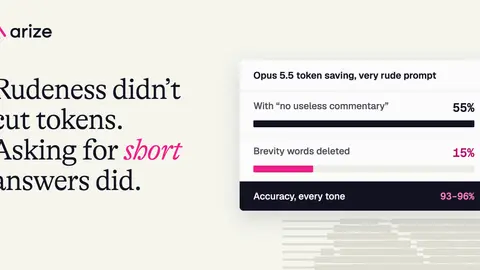
Does being rude to AI improve answers or lower costs? We tested six models to separate prompt tone from brevity instructions and examine what changes. The post Does being rude to AI work? What 6 models revealed appeared first on Arize AI.
Evaluate open models with Together AI in Arize AX. Compare model performance, run LLM-as-a-Judge evaluations, and explore lower-cost alternatives. The post Together AI integration: Evaluate open models and optimize evaluation costs in Arize AX appeared first on Arize AI.
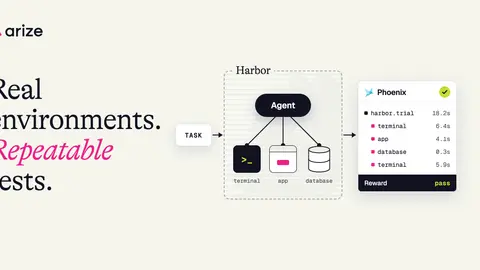
Build a reproducible benchmark, compare tool use across agents, and test whether a description change reduces unnecessary work while preserving outcomes. The post How to test agent tool descriptions with Harbor and Phoenix appeared first on Arize AI.
Evaluating OpenRouter? It routes model calls across providers. Vivgrid runs enterprise agents — every model on one key, cloud-hosted tools, and evals.
Automated evals can score every agent session, but they do not automatically reflect what your team considers a good outcome. That takes human judgment. The post Alignment is a human-AI workflow: how Custom Views make agent review possible appeared first on Arize AI.
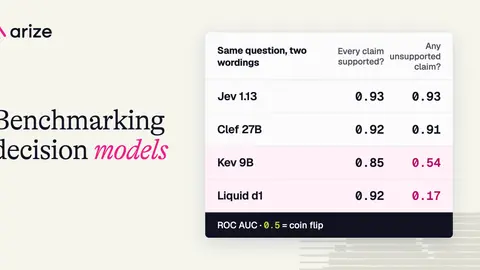
On 15 September, TypeSafe released Jev, and within a few weeks about 10 companies had shipped something that works the same way. OpenAI, Liquid, Cloudflare, AWS and PostHog all launched one, and an open clone called Kev showed up on Hugging Face in between.
Real desktop interaction data is hard to get. Computer use agents can capture it at scale and turn it into synthetic datasets for training and evaluating AI. Learn the tradeoffs and how to start.
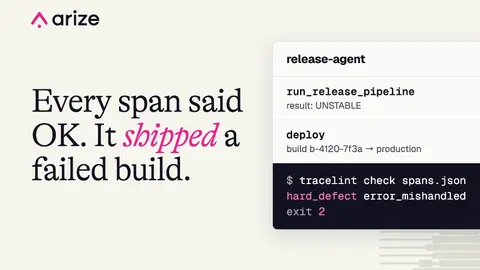
Some agent failures are already in the trace. tracelint proves them on Phoenix OpenInference spans and fails CI, without an LLM judge. The post What agent traces can tell you without an LLM judge appeared first on Arize AI.
See how Arize uses Harbor and Phoenix to benchmark AI agents, MCP servers, skills, and CLIs in reproducible sandboxes, then inspect traces and annotations. The post How we benchmark AI agents and tools with Harbor and Arize Phoenix appeared first on Arize AI.
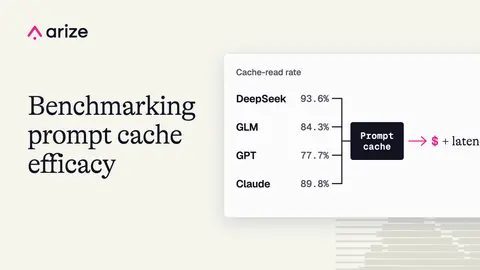
We benchmarked prompt caching across DeepSeek, GLM, GPT, and Claude using Harbor evals and Phoenix traces, so we could compare cache reuse, estimated cost, and latency on the same multi-turn shopping assistant agent.
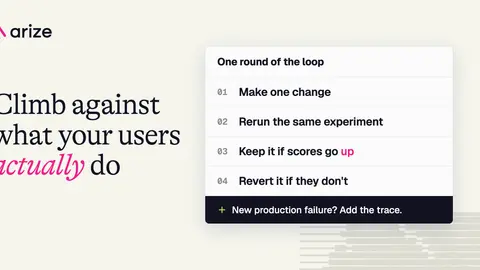
Anthropic's Claude hillclimb loop designs evals and improves agents one change at a time. Here's how to run that loop against production traces in Arize AX. The post Claude’s hillclimb loop for AI agents: start with production traces appeared first on Arize AI.
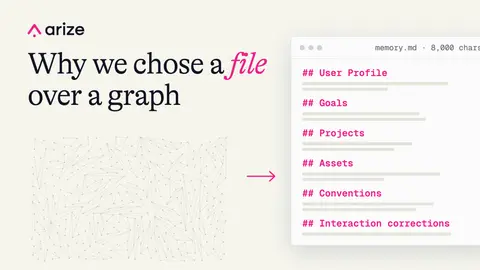
How we built long-term memory for Alyx: why we chose one 8,000-character file over retrieval and knowledge graphs, and how we tested it. The post How we built long-term memory for Alyx: why we chose a file over a knowledge graph appeared first on Arize AI.
This year agents at OpenAI, Anthropic, and Google escaped environments meant to contain them. What decided severity was time-to-detect and time-to-kill, from 12 minutes to seven months. NVIDIA's Open Agent Safety Platform puts a kill switch in hardware the agent can't reach.
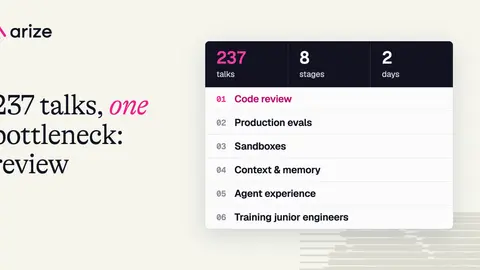
After 237 talks across eight stages, code review emerged as the bottleneck for AI-generated code. Here are the production eval, sandbox, context, and agent experience themes that kept showing up.
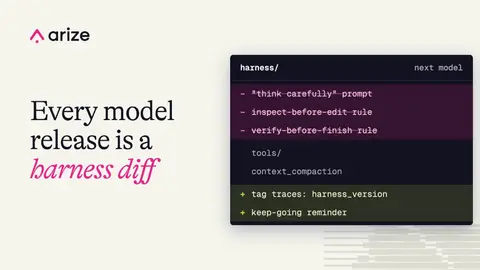
Harness distillation can train general scaffolding into a model. The harness that remains is the part tied to your tools, data, users, and environment. The post Are agent harnesses dying? What harness distillation changes appeared first on Arize AI.
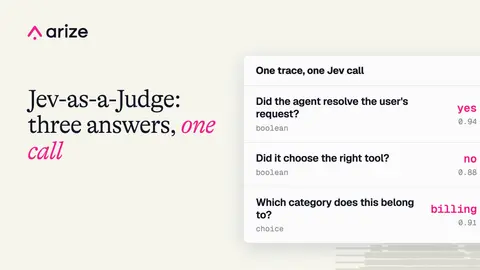
Arize AX now integrates directly with TypeSafe AI, bringing native Jev-as-a-Judge evaluations into the Arize evaluation workflow. The post Evaluate production traces with Jev-as-a-Judge directly in Arize AX appeared first on Arize AI.
Showing 18 of 30 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts