
Few-Shot Text Classification with Scikit-LLM
Leveraging Scikit-LLM for one of the simplest yet most practical text classification tasks utilized in the modern AI landscape: few-shot classification.
KDnuggets6 min read
32 stories
Leveraging Scikit-LLM for one of the simplest yet most practical text classification tasks utilized in the modern AI landscape: few-shot classification.
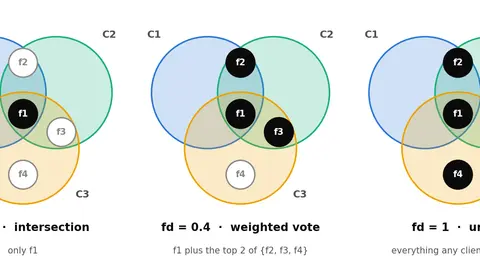
Hospitals, banks, and edge devices can agree on which features matter by sharing votes instead of rows, runnable in NVIDIA FLARE and Flower The post Voting on Features: Federated Feature Selection Without Sharing Data appeared first on Towards Data Science.
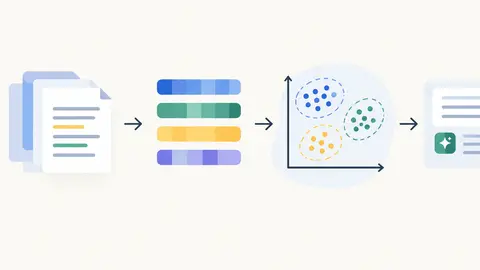
In this article, you will learn how to build a lightweight, end-to-end RAG pipeline using scikit-learn for vector retrieval and open-source models for embeddings and...
Most people learn Flask by reading documentation, then get stuck at “what do I build now?” A Flask project is the fastest way to close that gap, you write real routes, connect a real database, and ship something you can link to on your resume.
Making Intent Routing Explainable: Calibrated Probabilities, Decision Records and a Four-Tier Cascade
When not Modeling is the Pragmatic Decision An anonymized forecasting case reconstructed with synthetic data: regime shifts, pretrained models and production judgment A few months ago I was involved …
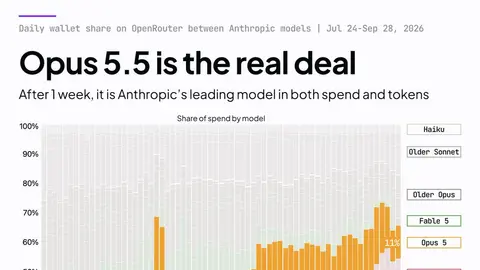
Checking in on Opus 5.5 ~1 week after launch. It's the #1 model in share of spend and share of tokens among Anthropic models on OpenRouter Switching from Opus 5 has been particularly rapid
Detect hidden shifts in feature relationships with adversarial validation and scikit-learn The post How to Catch Data Drift When Every Feature Looks Normal appeared first on Towards Data Science.
A quiet day lets us discuss the work behind the scenes - now open for business!
scikit-learn is one of the most widely used tools in data science, counting over 200 million downloads every month. You may know it as the Python library, but behind the code there is a global community that develops, maintains, and sustains it for the benefit of all data scientists all over the…
We talked to Google’s Oscar winning “Giganerd” about automating science, solving climate change, and how future generations can contribute to science in the age of superintelligent AI
In this article, you will learn what embedding drift is, why it matters for production large language models, and how to implement two practical techniques...
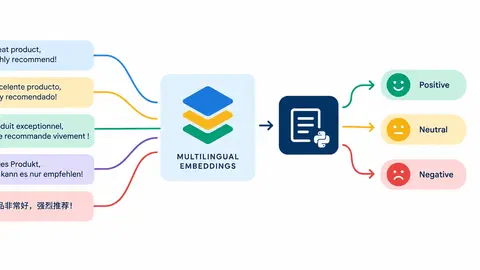
In this article, you will learn how to build a multilingual text classification pipeline using multilingual large language model (LLM) embeddings and Scikit-learn, without training...
Machine learning model deployment moves trained models to production. Learn deployment patterns for ML models, CI/CD, and feature-flag rollouts.
pip install lightpanda gives you a headless browser and its Python bindings in one command, browser included. Scrape JavaScript-rendered pages and hand the data straight to pandas.
Machine learning can sound much more complicated than it actually is. You hear words like models, training, features, datasets, predictions, and algorithms, and it can feel like you need a PhD in math
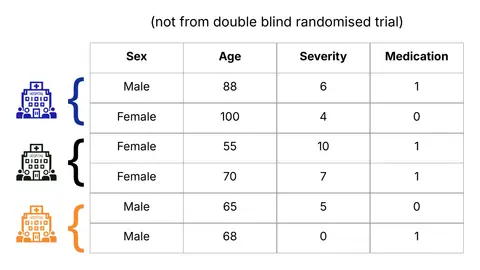
Author: Stefanie Senger This blog post is a cross-post of a Probabl blog post and based on a talk given at EuroSciPy 2026 in Kraków (slides).
Scikit-learn 1.9 release is out, and it comes with solid improvements to many existing estimators, making them faster, more stable, handling missing values, adding GPU support… The release also enhances the estimator displays in notebooks, and introduces a callback mechanism that opens the door to…
Showing 18 of 32 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts